
Definition: What consistency means in sports prediction
Consistency is the repeated application of the same vetted decision process that produces small, positive advantages over many independent predictions. In sports forecasting, consistency is not an emotional promise of constant wins; it is a practice where selection criteria, unit sizing, and review routines yield a reliable edge when applied across a large sample of plays. Why Consistency Matters More Than One Big Winning Day when you want to build a record that evaluation programs can judge.
Think of consistency as the discipline to make the same quality decision today that you made yesterday, and to measure outcomes in the same units. Contrast this with a single big win, which is often the product of variance rather than repeatable skill. Over many predictions, a modest edge that is applied consistently tends to produce clearer evidence of skill, because outlier outcomes have less influence on overall performance than they do in short samples.
Platforms that evaluate participants focus on metrics that reward steady gains and controlled risk. Typical measures include win rate, profit per play scaled to a common unit, and drawdown limits that stop extreme losses. Those metrics favor processes that reduce variance and emphasize repeatable advantage rather than one-off results. By understanding how consistency appears in these measures, a predictor can design habits and rules that are verifiable and defensible during an evaluation phase.
To illustrate in simple terms, imagine two forecasters. One posts a massive gain in a single event and then returns to breakeven across many small plays. The other consistently adds small gains every week. Over time, the second forecaster will present a cleaner, more persistent track record, which is more useful for judgment in settings where steady performance is required.
Start with one measurable metric this week
Track just one metric this week, such as units won per selection, and note it after each contest.
Consistency versus a single big win
When we say consistency rather than chasing a single big win, we mean maintaining process integrity and sizing discipline even when outcomes feel unfavorable. A single big win can mask underlying weaknesses in selection criteria or staking rules. By emphasizing process, you reduce the chance that luck will be mistaken for replicable skill.
How consistency shows up in performance metrics
Consistency shows up as a modest but positive unit ROI per selection, stable hit rates over reasonable samples, and limited drawdown depths relative to bankroll. You will also see fewer extreme streaks and a smoother equity curve when results are plotted. Those patterns are exactly what many skill-based challenge models look for when they judge who advances.

Why consistency matters more than one big winning day
There are practical advantages to steady returns in prediction work. Repeated small edges compound in a dependable way because each small positive expectation, when applied repeatedly, increases the chance that the long-run outcome favors the predictor. Relying on rare outsized wins is a fragile approach: the event that produced the big day may not recur, and the behavior rewarded by a single win can encourage reckless staking in the future.
Psychology plays an outsized role in decision-making under variance. After a big loss, many predictors feel pressure to increase stake sizes to chase losses; after a big win, they might overestimate their edge and take larger positions. Both reactions break discipline and inflate variance, which harms performance during structured evaluations that enforce drawdown or daily loss rules. Maintaining consistent unit sizing and documented selection criteria helps prevent emotional swings from driving decisions.
For participants in funded challenge models, steady performance signals that rules and risk controls are being followed. These programs often use drawdown thresholds and required progressive targets to assess readiness for funded accounts, and they reward predictability and discipline over sporadic success. Emphasizing repeatable decision-making aligns a predictor's behavior with the expectations of such evaluation frameworks.
The math of repeated small edges
A small positive edge, applied consistently, reduces uncertainty in the long run because it increases expected value across many independent trials. While any single prediction has high variance, the aggregate of many independent, identically executed decisions reveals the underlying expectation more clearly. Consistent application of a small edge also makes it easier to estimate required sample sizes and to detect structural problems in your approach, since outcomes will trend toward the expected direction if the edge is genuine.
Psychology and behavior under variance
Variance amplifies emotional responses. Predictors who chase big wins often change staking after streaks, which converts variance into a systematic source of ruin risk. By contrast, adopting rules that curb impulse sizing and enforce cooldowns after extreme outcomes reduces the chance that emotion will compound variance into catastrophic drawdown. The psychological advantage of consistency is that it creates predictable behavior, which itself is a stabilizing factor for long-term performance.
Core framework: How to measure and build consistency
Start with a concise set of metrics and a fixed process for collecting them. At minimum, capture unit ROI per selection, hit rate, average outcome size, maximum drawdown in units, and streak statistics such as longest losing and winning runs. Keep every entry in a single ledger or spreadsheet so comparisons are straightforward and you avoid fragmented records.
Once metrics are tracked consistently, create a monthly review ritual that asks three questions: what changed in selection criteria, what changes occurred in opponent or market conditions, and what staking decisions materially affected variance. This routine turns raw results into actionable improvement steps and ensures gradual, controlled adaptation rather than ad hoc reaction to isolated events.
A simple spreadsheet template to record key prediction metrics
Keep entries brief
Use the metrics to set realistic performance goals. For example, decide on acceptable ranges for unit ROI and maximum drawdown before you begin a new challenge. Those thresholds should be based on prior behavior rather than wishful targets. When you measure against realistic benchmarks, you reduce the temptation to chase volatility and you provide clearer signals for when to tinker with your approach.
Key metrics to track
Unit ROI per selection normalizes different stake sizes and makes individual picks comparable. Hit rate tells you how often a selection is successful but does not capture edge alone; combining hit rate with average payoff per hit reveals expected value more completely. Maximum drawdown is critical during evaluation phases because it signals your worst-case temporary loss relative to starting units. Track streak lengths to understand how variance presents itself for your specific method.
A simple routine for monthly reviews
Set a short monthly checklist: export your recent picks, compute unit ROI and drawdown, note any shifts in strategy or market conditions, and decide on one measured change to test next month. Keep the changes small so you can attribute effects to single factors. Document why you made each change and what you expect to observe; that habit makes subsequent reviews more diagnostic and less speculative.
Risk controls and bankroll rules that favor consistency
Bankroll management is the mechanism that translates consistent decision-making into durable account progress. Two practical staking approaches that reduce volatility are flat units and proportional staking. Flat units assign the same unit size to each selection to limit the impact of any single outcome. Proportional staking sets unit size as a fixed percentage of bankroll so position sizes scale sensibly with account size.
Drawdown limits serve as guardrails during evaluation challenges. By explicitly defining and respecting a hard drawdown threshold, you prevent small slippages from becoming account-ending losses. Set both per-event exposure caps and time-based rules, such as a daily loss limit, to make sure you never risk a disproportionate share of your bankroll in a single stretch of poor outcomes.
Platforms with evaluation stages typically penalize large, erratic swings. Strict rules not only protect your virtual funds but also present a stable record that evaluators can judge. Discipline in staking and drawdown respect help you convert a good selection process into demonstrable, low-variance results that meet challenge conditions.
Staking plans that reduce volatility
Flat staking is straightforward: pick a unit size and use it consistently. This method makes outcomes easier to compare and keeps single losses predictable. Proportional staking, by contrast, is dynamic: if your bankroll grows or shrinks, your unit sizes scale accordingly. Both approaches lower the chance that a single event will dominate your record, which is important in programs where maximum drawdown is tracked and enforced.
Using drawdown limits effectively
Define a drawdown limit before you start a challenge and treat it as inviolable. If you breach the limit, pause to run a review rather than attempting immediate recovery with larger stakes. That enforced pause reduces emotional decisions and gives you space to analyze whether a strategic adjustment or a temporary cooldown is the correct response.
How to choose strategies that prioritize steady returns
Select strategies by evaluating historical variance, average edge per play, and the sample size needed to reach statistical confidence. A model with a small edge and low variance may be preferable to one with higher expected value if the latter requires enormous samples to realize its advantage. The key is to match strategy characteristics to your evaluation horizon and risk tolerance.
When you evaluate strategies, consider correlation between plays. Highly correlated selections increase effective variance because several losses or wins may arrive together. Diversifying uncorrelated ideas reduces streak risk and improves the chance that your aggregated results reflect underlying skill rather than clustered outcomes.

FundedPlays and similar funded challenge models reward consistent, disciplined forecasting because they aim to identify repeatable skill under controlled conditions. The platform model organizes evaluation objectives, drawdown rules, and progression criteria so that steady performers are easier to identify and promote. Understand the rules for any challenge you enter and align your strategy to those constraints to reduce the risk of disqualification from rule violations.
Criteria to evaluate a strategy
Ask four pragmatic questions when assessing a plan: what is the historical variance, what edge does each play offer, how many selections are needed to validate the edge, and how correlated are the selections? Favor strategies that require fewer selections to show a stable edge and that keep correlation low across events.
When to prefer low-volatility approaches
If your evaluation window or drawdown constraints are tight, choose low-volatility approaches. These strategies may offer slower growth but increase the likelihood that your recorded performance stays within acceptable thresholds. If you plan to scale later, use early-stage low-volatility performance to build a clean track record before widening exposure within controlled guardrails.
Decision checklist for evaluation challenges
Pre-challenge preparation sets the tone for consistent performance. Before you start, define unit size, review past sample performance, and set explicit stop-loss and daily limits. Read the challenge rules carefully so you can align behavior with qualification and withdrawal conditions rather than operating by intuition alone.
During the challenge, keep disciplined records of every pick, avoid increasing size after losses, and respect drawdown thresholds. Small recorded habits make big differences: logging the rationale for each selection prevents hindsight-driven changes, and a fixed daily limit prevents emotional sizing escalation late in a session.
Pre-challenge preparation
Make a checklist that includes defining unit size relative to challenge capital, running a quick review of recent samples, and writing down the exact acceptance criteria for a pick. Clarify stop-loss and daily limits so you have a ready guide when variance turns unfavorable.
In-challenge rules to follow
During competition, commit to recording every pick, noting stake size and reason, and refraining from impulsive stake increases. If you hit pre-defined drawdown levels, trigger a planned review instead of attempting to recover immediately. That discipline helps keep results aligned with the expectations of evaluation frameworks.
Common mistakes that destroy consistency
Several behavioral traps are common among predictors. Chasing losses by increasing stake sizes after a bad run, overconfidence after a winning streak, and frequently changing methodology during short samples are typical examples. Each of these behaviors increases variance and undermines the evidence you need to show repeatable skill.
Poor record keeping and inconsistent unit reporting are frequent technical errors. When you do not log units consistently, you cannot compare different periods or strategies accurately. Missing fields, inconsistent unit definitions, and fragmented notes make it nearly impossible to diagnose whether a change in results stems from noise or from an actual methodological improvement.
Prioritize repeatable selection criteria, fixed unit sizing, disciplined drawdown controls, and a routine review process so that your track record reflects sustainable skill rather than luck.
Corrective actions are straightforward: set hard rules against increasing size after losses, maintain a consistent approach for a predefined validation window, and standardize your logging template so all entries are comparable. Those small operational fixes remove many excuses for short-term reactive behavior.
Behavioral traps
Chasing losses and overconfidence both depend on flawed short-term inference. A losing streak does not prove the method is broken, nor does a winning streak prove it is flawless. Keep the decision rules fixed for the agreed validation window and then review results with your documented checklist, not with impulses or anecdote-driven reasoning.
Technical errors in record keeping
Common mistakes in logging include inconsistent unit definitions and incomplete outcome notes. Solve these by using a single spreadsheet with fixed columns and by always recording the same fields. This lets you calculate unit ROI and drawdown reliably and compare different time windows without confusion.
Practical scenarios: Applying consistency on a funded challenge platform
Scenario A is a conservative season-long model that focuses on small-value edges across many games. The approach uses flat units, strict daily limits, and a monthly review cadence. Over a 90-day evaluation, the model aims to show steady, positive unit ROI with shallow drawdowns that fit typical challenge requirements. The main advantage of the conservative model is that it minimizes the chance that a few large swings will mask the underlying skill signal.
Scenario B is a selective approach that identifies high-value props but caps exposure per event. This method accepts higher variance per pick but limits its contribution to the overall record by restricting units per selection and by diversifying across unrelated markets. The objective is to preserve some upside while preventing a single error from causing a disqualifying drawdown.
Scenario A: conservative season-long model
Under the conservative model, pick selection follows a repeatable checklist and unit size remains flat. Each week the predictor records every pick and the outcome, computes unit ROI, and notes any divergence from expected conditions. If drawdown approaches a preset threshold, the protocol calls for pausing new exposure and performing a focused review rather than increasing risk to recover losses.
Scenario B: selective high-value props with unit limits
In the selective model, the predictor applies tighter filters to choose fewer plays with clearer edges. Each play is capped at a defined fraction of the daily unit budget so a single hit or miss does not dominate. This preserves the ability to capture occasional outsized opportunities without letting them dictate the account trajectory over the evaluation period.
Both scenarios illustrate that consistent application of rules and explicit caps on exposure are the common ingredients for producing a credible track record. The choice between them depends on how tight the evaluation window is and how the platform measures eligibility.
Tools and habits to maintain consistent performance
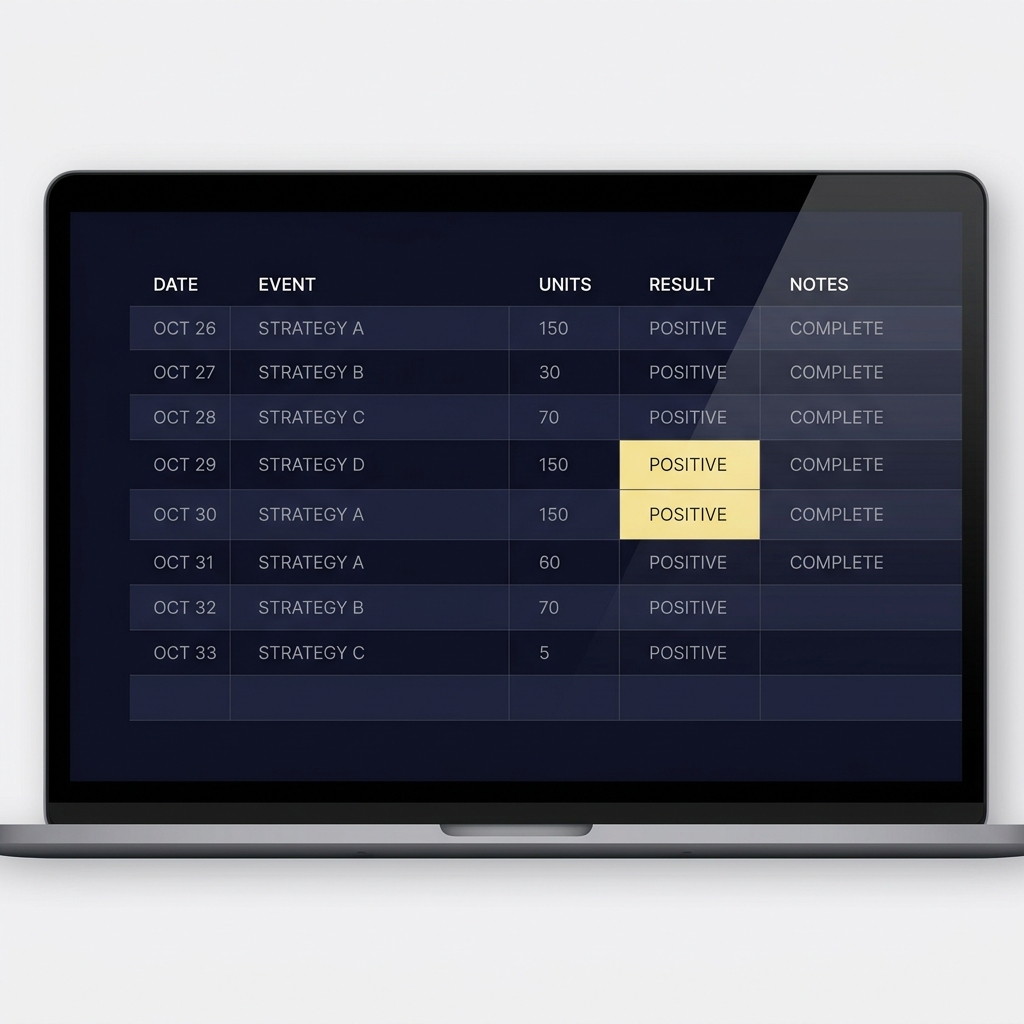
Keep a simple tracking spreadsheet with essential columns: date, event, units risked, result in units, rationale, and notes. That small structure provides everything needed to compute unit ROI, hit rate, and drawdown. Avoid collecting excessive fields, which makes logging tedious and increases the chance of missing entries.
Daily habits matter. Before making picks, run a short pregame scan to confirm unit sizes and any new information that might change the odds. After results, add a brief postgame note explaining deviations from expectation. Weekly habits include reviewing losing sequences, checking whether the same error repeats, and adjusting unit sizing only after a documented analysis rather than in reaction to feelings.
Simple tracking spreadsheets and logs
The minimum useful spreadsheet contains the essential fields and a consistent unit convention. Use formulas to compute cumulative units, current drawdown, and simple moving averages of unit ROI. Those computed fields transform raw logs into actionable charts that reveal whether your process is converging to a steady advantage.
Daily and weekly habits
Daily routines keep errors small. A pregame check ensures you are not increasing trivial risks; a postgame note captures early signals; and a weekly review consolidates patterns into a single decision about unit sizing or selection filters. Habit formation reduces the cognitive load of each decision and increases the odds that you will follow your documented process even under pressure.
How to test and iterate without destroying your bankroll
Adopt a small parallel A/B test approach when you want to change a strategy. Run the new variation on a limited fraction of your unit allocation so the majority of your capital continues under the proven method. This allows you to compare outcomes contemporaneously without exposing the entire account to unproven ideas.
Define explicit success and failure criteria for any test before you start. For example, a test might be deemed successful if it outperforms the control by a pre-specified margin over a fixed number of selections. If the test fails to meet the criterion, stop it, document why it failed, and return to the control method or iterate with a smaller scope.
A safe A/B approach to strategy tweaks
Split a small portion of your daily units to try the tweak while keeping the rest under your baseline rules. Maintain identical logging for both arms so you can compare unit ROI, hit rate, and drawdown cleanly. Limit the duration of the test so results do not drift beyond the period where decisions are comparable.
When to stop and re-evaluate
Stop a test when it breaches predetermined failure criteria or when it runs long enough to make the results statistically meaningful given your average selection frequency. If emotional pressure builds to act on interim noise, pause the experiment and conduct a short review rather than abandoning the test midstream.
When a big winning day still has a place
There are legitimate moments to take larger positions, but those should be described by clear criteria rather than intuition. Examples include rare information advantages or arbitrage opportunities where expected value materially exceeds normal selections. Even then, cap exposure so one win or loss cannot derail your progress.
Integrate opportunism with discipline by using conditional rules: require written justification, set a maximum stake cap for opportunistic plays, and log why the play qualified as exceptional. That way, you capture upside without letting a single event dominate the evaluation narrative.
Recognizing legitimate high-value opportunities
High-value opportunities are those where your analysis shows significantly higher expected value than usual, supported by independent checks and low correlation with your other selections. Treat these plays as exceptions and not as changes to your baseline process.
Balancing opportunism with discipline
Use stake caps and written pre-commitments to keep opportunistic bets from becoming a habit. That preserves the integrity of your track record while allowing occasional, justified departures from standard sizing rules.
Checklist: Building a 90-day consistency improvement plan
Week one: set up your logging spreadsheet, define unit size, and establish drawdown and daily limits. Week two: run your baseline selections for a sample period and compute initial metrics. Week three and four: conduct the first monthly review and make only one small, documented change if warranted.
Weeks five through twelve: follow a repeating cycle of four weeks of baseline execution and one focused monthly review, with specific milestones for unit ROI and drawdown targets. Keep changes small and traceable. Document every change and its rationale so you build a useful decision history rather than a collection of anecdotes.
Week-by-week milestones
Design milestones that are realistic and based on prior performance. For example, aim to reduce maximum drawdown relative to your last period, or to show steady unit ROI without increasing stake sizes. Use those concrete checkpoints to decide whether to continue, refine, or pause adjustments.
Metrics to monitor and endpoints
Monitor unit ROI, hit rate, drawdown, and streak length. Define endpoints such as a measured improvement in unit ROI or a reduction in maximum drawdown before increasing exposure or changing the strategy materially. Those endpoints protect you from premature scaling or chaotic rule changes driven by short-term outcomes.
Conclusion: How to think about success on skill-based platforms
Steady, disciplined performance almost always outperforms chasing a single big day for entrants in skill-based challenge environments. Consistency creates a record that evaluators can interpret, reduces emotional decision making, and aligns your behavior with the rules and constraints many platforms impose. Maintain a simple, repeatable process, and let incremental improvements compound into a reliable track record.
Respecting rules, keeping thorough records, and treating drawdown limits as non-negotiable are practical ways to make progress without gambling the account on a single event. Skill matters, but variance is real; your goal is to design a process that reveals skill despite noise, not one that depends on lucky outcomes.
Next steps include implementing the 90-day plan, choosing a low-friction logging tool, and committing to the monthly review rhythm. Over time, consistent behavior will produce clearer evidence of your predictive ability and better position you to succeed in structured challenges.
Consistency becomes visible over many independent selections; expect to evaluate patterns after several weeks or months depending on selection frequency.
Yes, test changes on a small fraction of your units with clear success and failure criteria to avoid jeopardizing overall progress.
Unit ROI per selection is the most practical single metric because it normalizes stake sizes and summarizes edge over time.
References
- https://insights.matchbook.com/betting-strategy/variance/
- https://www.bettoredge.com/post/variance-in-sports-betting-explained
- https://www.sportbotai.com/blog/understanding-variance-in-sports-betting-ai-data-predictions
- https://www.fundedplays.com
- https://www.fundedplays.com/blogs
- https://www.fundedplays.com/blogs/how-fundedplays-evaluations-work
- https://www.fundedplays.com/challenges