
Quick answer: what sustainable sports trading actually means
Sustainability in a sports trading strategy means one simple thing in practice: a demonstrable, repeatable positive expected value after accounting for bookmaker margin, combined with process controls that keep risk, staking and behavior in check. In other words, a sustainable approach shows evidence it beats the market net of the overround and does so under disciplined rules rather than by chance or shifting risk profiles.
The high level pillars are clear and interlinked. First, robust out-of-sample validation establishes that predictive skill is real. Second, sensible staking and bankroll rules prevent ruin and reduce volatility. Third, reliable measures of edge, like closing line value, show whether pricing advantage persists. Fourth, continuous monitoring and governance detect model decay or data problems. Finally, responsible participation rules limit loss-chasing and ensure long-term discipline. When combined, these elements form a long-term framework for sustainable sports trading.
It is important to be explicit: sustainability is not a promise of profit. Results depend on model skill, market conditions, discipline and consistent rule-following, and individual outcomes will vary.
CSV template and scoring script for disciplined validation
Use with time-series folds for scoring
Definition and context: the components of a sustainable strategy
At its core, a sustainable strategy must deliver positive expected value net of bookmaker overround, because markets include a built-in margin that participants must overcome to be viable long term. Demonstrable edge means the expected return after fees and margins is positive and consistent across holdouts and time windows; without that, apparent gains are likely to evaporate when tested out of sample. For context on market margins and industry conditions, consult the relevant regulatory statistics.
UK Gambling Commission industry statistics
Validation and process controls are equally important. A plan that documents rules for model training, out-of-sample testing, fixed staking rules and governance produces much more reliable evidence than ad hoc backtests. Operational components should include written rules, pre-specified budgets and drawdown limits, timestamped trade logs and a monitoring dashboard. These pieces let practitioners separate genuine signal from artifacts of overfitting and data leakage.
Funded-challenge platforms provide a structured environment where participants can practice discipline, execute strategies against simulated or virtual funded accounts and measure performance without immediate real-money execution. These environments can help test process controls and measure how a plan performs under defined rules without implying any guarantee of outcomes or earnings.
Core framework: validating models and avoiding overfitting
Why time-series cross-validation matters
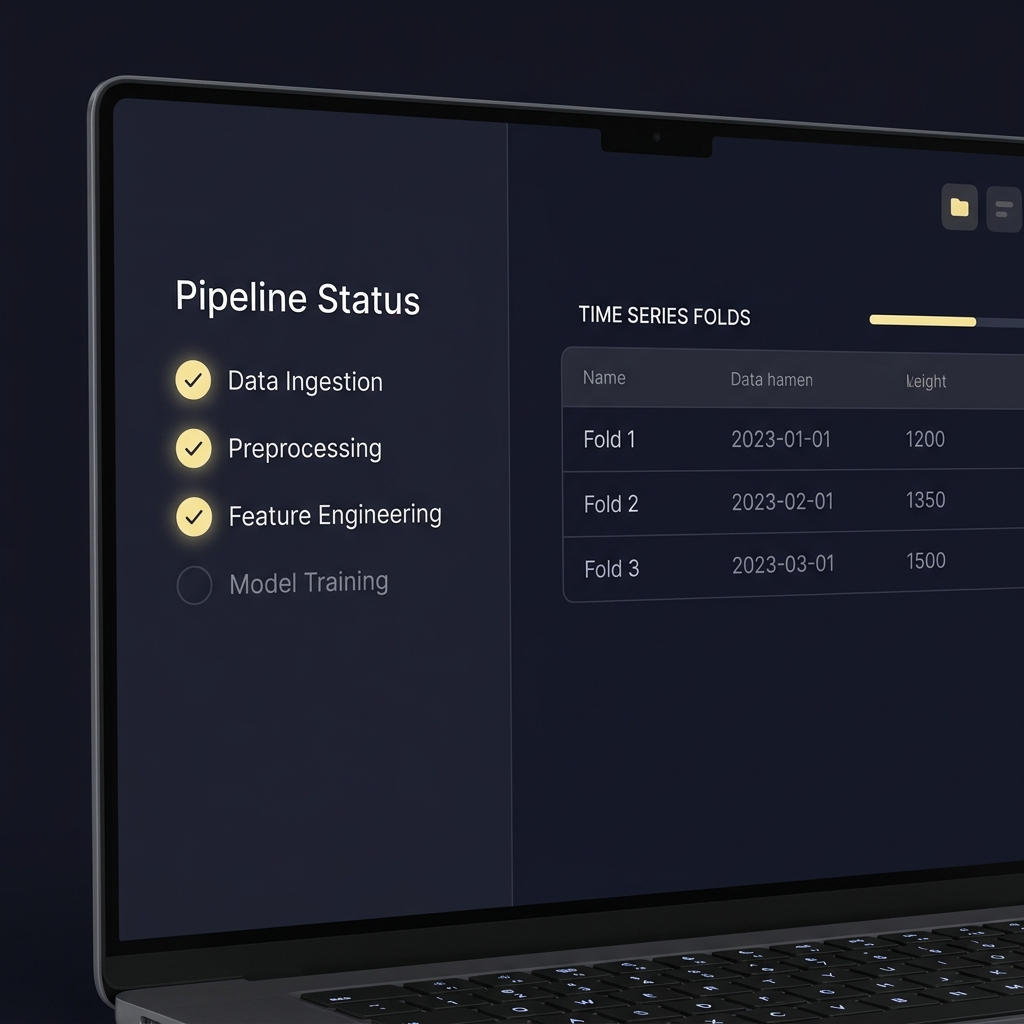
When markets move in sequence, standard random splits can produce overly optimistic skill estimates by leaking future information into training. Time-series cross-validation treats data as ordered, creating folds that preserve chronology so models are evaluated on truly unseen future periods. This approach reduces look-ahead bias and gives a clearer estimate of how a model will perform when deployed.
Time series cross-validation guide

Practically, implement a rolling-origin evaluation where the training window grows or slides forward and each fold predicts the next holdout window. Record scores for each fold and inspect variability across seasons and market segments rather than relying on a single aggregate statistic. That variability often reveals regime sensitivity or overfitting to narrow conditions. See Rob Hyndman's cross-validation discussion for an alternative perspective on implementation details: Cross-validation for time series.
Using proper scoring rules to judge probabilistic forecasts
For probabilistic predictions, proper scoring rules like log loss and the Brier score reward well-calibrated probabilities and penalize overconfident errors. They are preferable to raw accuracy because they capture both calibration and sharpness, two qualities that matter when you convert probabilities into stakes or compare models across markets.
Strictly proper scoring rules paper
In practice, compute scores on each time-series fold and summarize rolling performance. Compare model variants with the same scoring rule to select those that generalize better. Keep the scoring metric fixed throughout evaluation so model selection is consistent and not tuned to a changing objective.
A sustainable system combines demonstrable positive expected value net of market margin, disciplined out-of-sample validation, conservative and fixed staking rules such as fractional Kelly, continuous monitoring with KPIs like log loss and closing line value, and documented responsible participation safeguards.
Decision rules: bankroll, staking and position sizing
Kelly criterion and why fractional Kelly is common
The Kelly argument shows how to size positions to maximize long-term capital growth under ideal assumptions, but those same calculations can produce high volatility and large drawdowns. Many practitioners prefer fractional Kelly, which scales down full Kelly stakes to reduce variance and improve psychological manageability while retaining some growth advantage compared to fixed-percentage staking.
For most traders, fractional Kelly values between 0.25 and 0.5 are common because they smooth returns and make drawdown recovery more predictable. The right fraction depends on model confidence, correlation between bets, and personal or institutional risk limits. Whatever rule is chosen, keep it fixed during evaluation windows to avoid data-snooping through stake tuning.
Practical rules for drawdowns and stop conditions
Documented drawdown limits and stop conditions protect capital and enforce discipline. Typical operational rules include a maximum percent drawdown before a mandatory review, per-event staking caps, and an emergency pause after a sequence of losses to force a review of data and assumptions. These rules map directly to responsible participation measures and support long-term continuity.
Linking staking discipline to psychological resilience is important. Fixed rules reduce reactionary changes during bad runs, and written procedures for review reduce the chance of chasing losses. Those habits make it more likely that genuine edge compounds rather than erodes through inconsistent behavior.
Edge and market realities: measuring net expected value and closing line value
Bookmakers price in an overround, so any strategy must deliver positive expected value net of that margin to be sustainable. Measuring raw returns without adjusting for market margin gives a misleading picture of true edge, and tests that ignore margin are prone to false positives when applied to regulated markets.
UK Gambling Commission industry statistics
Closing line value, the difference between the odds obtained and the market closing odds, is a practical KPI for pricing edge. Regular positive CLV suggests that a predictor is adding value relative to market movement, while flat or negative CLV signals weak or absent edge. Use CLV as a complement to score-based validation rather than as a sole proof of profitability.

When computing CLV, be careful to align timestamps and use the market odds that were available at bet placement and at market close. Using stale lines or mismatched time sources can create artificial CLV that does not reflect true execution advantage.
Monitoring and governance: KPIs, alarms and ongoing validation
Put a small set of KPIs at the center of monitoring: a proper scoring rule like Brier or log loss, rolling CLV, rolling returns and drawdown, and segmented hit rates by sport or market. Track these metrics on rolling windows and inspect for consistent degradation rather than reacting to single-period noise.
Strictly proper scoring rules paper
Automated alarms should trigger reviews when metrics cross pre-specified thresholds. For example, a sustained rise in log loss, a negative trend in CLV, or an unexplained increase in variance should prompt scheduled revalidation. Re-run full time-series cross-validation when drift appears or when the operating regime changes materially.
Time series cross-validation guide
Governance also includes record-keeping and accountability. Keep immutable logs of model versions, data snapshots and staking decisions so reviews can reconstruct what was active during any period. These records reduce ambiguity when evaluating performance and support disciplined, evidence-based changes.
Embedding responsible participation and process safeguards
Responsible gambling principles translate well into operational safeguards for sports trading. Predefined budgets, per-event limits, and explicit anti-chasing rules limit exposure and discourage reactionary behavior during losing sequences. These controls protect both capital and participant welfare while supporting long-term strategy testing.
Responsible Gambling Principles
Documenting these safeguards is essential: write explicit budget rules, describe who may change them and under what conditions, and schedule periodic reviews. Clear documentation reduces ambiguity and helps maintain discipline when results are poor.
Plan limits and schedule a review with the FundedPlays Challenges framework
Document your limits now and schedule a formal performance review at the end of the next evaluation window to preserve discipline and prevent reactive changes.
Common mistakes and how to avoid them
Overfitting is common when validation uses random shuffles or when model selection targets in-sample metrics. The remedy is strict time-series validation and a separate holdout period that is never used for model tuning. Avoid data leakage by verifying that timestamps and all derived features are computed from information available at the prediction time.
Time series cross-validation guide
Another frequent mistake is adjusting staking mid-test based on short-term results. Changing stake rules during an evaluation invalidates conclusions about edge and increases the risk of false discovery. Fix staking rules during each test window and only adjust after pre-specified review conditions are met.
Poor timestamp syncing when computing CLV or using stale market snapshots can create artificial advantages. Use synchronized logs, prefer the earliest reliable source of market odds and store both placement and closing odds for auditing CLV calculations.
Practical example and checklist for testing a sustainable strategy
Here is a concise sample workflow to run a disciplined 90-day validation. Step 1: Define targets, fixed staking rules and drawdown limits. Step 2: Split historical data into rolling time-series folds and a final untouched holdout. Step 3: Train model variants and score them with log loss on each fold. Step 4: Record CLV and rolling performance during backtest. Step 5: Select models that show consistent out-of-sample skill and non-negative net EV after margin adjustments. Step 6: Run a simulated 90-day forward test without changing staking rules. Step 7: If metrics pass pre-specified thresholds, consider deployment into a funded-challenge environment or limited live execution with the same preserved rules.
Time series cross-validation guide or practical patterns such as those described at Machine Learning Mastery can help with fold design.
Checklist for a 90-day validation:
- Write a plan with objectives, metrics and fixed staking rules
- Prepare timestamped data and compute features only from available information
- Run time-series cross-validation and record fold scores
- Evaluate models with log loss and Brier score
- Compute CLV from placement to closing odds
- Fix staking using fractional Kelly or a conservative cap
- Set drawdown rules and automated alarms
- Run a forward simulated 90-day test
- Review results against pre-defined thresholds
- Document everything and schedule a governance review
Strictly proper scoring rules paper
Throughout the workflow, keep responsible limits active and document any deviations from the plan. A funded-challenge environment can be a useful next step to practice discipline under defined rules without implying any guarantee of qualification or rewards.
Measure probabilistic forecasts with proper scoring rules like log loss or Brier, and track closing line value over time to see if you consistently improve on the market; use time-series holdouts to avoid look-ahead bias.
Kelly provides a theoretical growth-optimal stake, but many practitioners use a fractional Kelly to reduce volatility and drawdowns; choose a fraction that fits your risk tolerance and keep staking rules fixed during testing.
Funded-challenge platforms are useful to practice discipline and process controls under defined rules, but they do not guarantee live performance or earnings; use them as a step before careful, limited live deployment.
References
- https://www.fundedplays.com
- https://www.fundedplays.com/blogs
- https://www.fundedplays.com/blogs/how-fundedplays-evaluations-work
- https://www.fundedplays.com/challenges
- https://www.gamblingcommission.gov.uk/statistics-and-research/publication/industry-statistics
- https://otexts.com/fpp3/tscv.html
- https://robjhyndman.com/hyndsight/tscv/
- https://www.stat.washington.edu/raftery/Research/PDF/Gneiting2007jasa.pdf
- https://www.investopedia.com/terms/k/kellycriterion.asp
- https://www.amazon.com/Logic-Sports-Betting-Ed-Miller/dp/1733643708
- https://www.ncpgambling.org/programs-resources/responsible-gambling/
- https://machinelearningmastery.com/5-ways-to-use-cross-validation-to-improve-time-series-models/