
What positive expected value and high win rate mean for sports predictors
Defining expected value in plain language
Expected value is a simple idea about what to expect from a repeated choice over time. It describes whether a selection gives you a long-term edge on average, not whether it wins every time. When thinking about expected value in betting, treat it as a directional guide: choices with a positive edge should make you better off if you can repeat them enough times and manage stakes sensibly.
Defining win rate and what it measures
Win rate is the share of selections that finish as winners. It measures frequency rather than size of returns. A high win rate feels reassuring because it produces regular small successes. But win rate alone does not show whether those wins cover the times you lose or pay fees, and it does not tell you about the upside when a selection pays more for a rarer outcome.
Why the two can point in different directions
It is common for a choice to have a high win rate but low or negative long-term value, or the opposite, because the two metrics focus on different things. One looks at how often you win. The other looks at how much you expect to gain on average. These two measures can diverge when payouts are uneven or when losses are larger than wins.

Variance and payout asymmetry are the mechanical reasons for this divergence. If a bet wins often but returns are small while occasional losses are large, the win rate looks good while the expected value can be poor. Conversely, a low win rate option that pays well when it wins can offer a positive edge over many trials even if it feels like a losing streak in the short term.
For participants in skill-based challenges, both concepts matter. Platforms that use evaluation rules reward consistent performance and may penalize big drawdowns. Understanding the difference between expected value and win rate helps you decide which metric to prioritize inside a structured progression system.
How positive expected value supports sustainable, long-term success
The intuition behind positive EV over many trials
Positive EV means each qualified selection gives you a small advantage that repeats. Over many trials, those small advantages add up into a reliable source of gains. That is why experienced predictors often talk about finding small edges and applying them with discipline rather than chasing rare big wins.
How small edges compound when applied consistently
When you consistently take selections with a positive edge, the day to day noise smooths out as sample size grows. This makes long-term outcomes more predictable, provided you avoid erratic stake sizing and respect risk limits. The mindset is about steady application of advantage rather than a string of visible short-term wins.
Sign up for FundedPlays challenge updates and guides
Sign up for challenge updates and practical guides to help you test EV-focused approaches in simulated accounts and structured evaluations.
In an evaluation or funded-simulation setting, prioritizing expected value encourages methods that are repeatable and documented. That habit helps with recordkeeping, review, and gradual improvement of your selection filters and staking rules.
Why a high win rate can feel safer but be misleading
Common patterns behind high win rate selections
High win rates often come from choosing favorites or options with low variance. Those selections win frequently because they rely on predictable outcomes. The trade-off is that the payout per win is often small, so many small wins must offset fewer, larger losses to be profitable.
Situations where win rate sacrifices value
When payout structures are asymmetric, frequent small wins can leave you exposed to outsized losses that eat into profits. A high win rate can produce a comfortable feeling while slowly eroding long-term value when the math behind each selection is unfavorable.
Psychology also plays a role. Short-term reinforcement from steady wins makes it tempting to increase stakes or ignore edge estimates. That behavior raises risk and can turn a seemingly safe style into a fragile one if conditions change.
Platform rules change relevance of win rate too. In some evaluation phases, avoiding large drawdowns is more important than maximizing theoretical edge. In those cases, a strategy that preserves account survival with a higher win rate may be temporarily preferred.
A decision framework: when to prioritize EV and when to favor win rate
Clarify your objective and time horizon
Step 1 is to state your objective clearly. Are you aiming to survive a short evaluation with strict drawdown rules, or are you trying to build consistent long-term growth? The time horizon shapes whether you need immediate survivability or long-run edge.
Map personal bankroll and volatility tolerance to strategy
Step 2 is to map bankroll size and how much variance you can tolerate. Smaller virtual or real bankrolls and low tolerance for drawdowns often push you toward conservative, higher win rate options. Larger bankrolls and appetite for volatility allow more room for low-win-rate, high-edge selections.
Prioritize positive expected value when you have a sufficient time horizon, a bankroll that tolerates variance, and rules that reward net edge. Favor a higher win rate when short-term survival or strict drawdown limits make consistent small wins the priority.
Step 3 is to read the platform rules on Funded Plays. Evaluation checkpoints, drawdown limits, and progression criteria can make win rate temporarily more valuable. When rules penalize wide swings, favor survivability while you meet checkpoints. When the environment rewards net edge across a long window, refocus on expected value.
How to combine both approaches in practice for funded challenges
A stepwise process for filters, staking, and review
Start with selection filters that remove obvious low-quality options while preserving the underlying edge. Add conservative stakes early in evaluation windows to limit drawdown risk, and increase size only after you pass key checkpoints and have documented consistent performance.
Monitoring checkpoints during evaluation runs
Define simple checkpoints to check both win rate and realized edge. Use short, rule-based reviews at fixed intervals so you avoid emotional reactions to noise. Record each decision and its rationale so you can revisit choices objectively after a run completes.

In a funded-simulation environment you can test hybrid approaches without risking real funds, using the platform rules to practice surviving checkpoints and demonstrating consistency. Keep tests focused, document every selection, and treat the evaluation as a controlled experiment rather than a sprint for short-term results. See how Funded Plays evaluations work for details.
Bankroll management and risk controls that work for both priorities
Practical position-sizing principles
Use fixed, repeatable position-sizing rules rather than ad-hoc stakes. Position sizing that scales with your available bankroll helps keep drawdowns manageable when variance materializes. Consistent rules reduce the chance of emotional overbets after a few losses.
Managing drawdowns and exits
Predefine drawdown rules and stop criteria so you have a clear plan to protect capital during a poor run. Simple exits and limits help you survive evaluation phases and preserve the option to iterate on strategy without severe setbacks.
simple performance log for challenge runs
update after each session
Diversifying across markets and selection types reduces exposure to a single source of tail risk. When switching from an EV focus to a win-rate focus, reduce stakes and tighten filters. When shifting back toward edge, document the reasons and increase size only after a clear pattern of success.
Common mistakes and how to avoid them
Emotional staking and chase behavior
One common error is increasing stakes after a loss to chase recovery. That behavior tends to magnify losses and destroys disciplined position sizing. Fix it with a rule that limits stake changes to scheduled reviews and keeps per-selection sizing consistent.
Overfitting systems to past results
Another frequent mistake is overfitting: tailoring rules so closely to past outcomes that they fail on new data. Avoid this by testing on out-of-sample periods and keeping selection logic simple enough to generalize.
Other errors include ignoring fees and vig, misreading small samples as proof of skill, or abandoning rules after a few outcomes. The remedy is clear documentation, a review cadence, and an accountability habit that forces you to justify changes with evidence rather than emotion.
Practical scenarios: choosing and testing a strategy without promises
Scenario A: prioritize safety and high win rate
Imagine you are in an early evaluation phase with a small virtual bankroll and strict drawdown limits. You might choose conservative markets and smaller stakes to build a steady win rate and preserve the account through checkpoints. The goal is survival and consistent progress.
Scenario B: prioritize long-term edge and low win rate
Now imagine you have a larger bankroll and the challenge window rewards net edge over many selections. You may accept a lower win rate for better long-term expectation, knowing that variance will feel uncomfortable in the short term but is tolerable with disciplined sizing.
How to simulate choices in challenge-style environments
Run short experiments in the simulation environment to observe how different filters and stakes behave. Keep the experiments small and repeatable, record every selection, and compare realized edge and win rate after a sufficient sample before drawing conclusions. For more guidance see the blog.
When a tested approach consistently underperforms, use an iteration checklist to decide whether to tweak filters or abandon the method entirely. Treat each test as an evidence-gathering exercise rather than a verdict.
Measuring what matters: metrics and review cadence
Core metrics to track and why
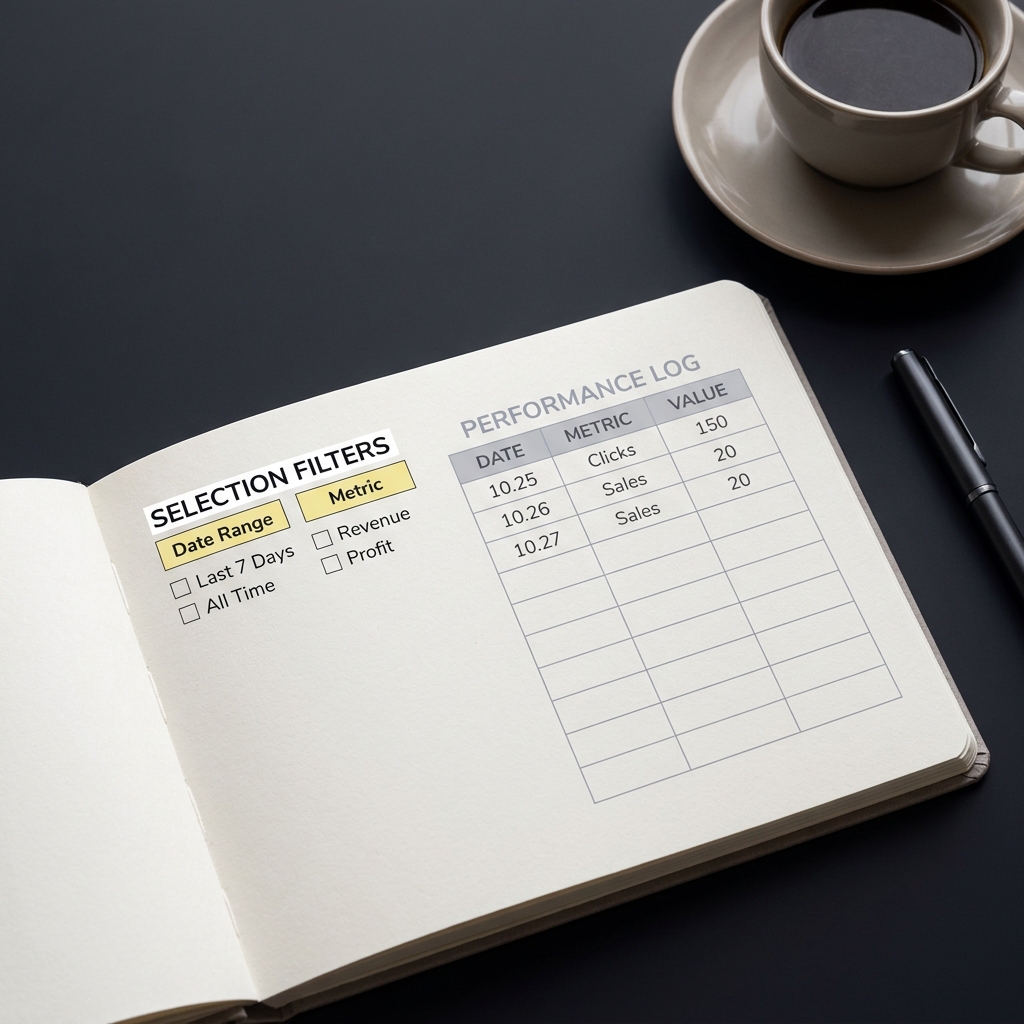
Track a compact set of metrics: win rate, realized edge estimates, average win and loss size, and drawdown depth. These describe both frequency and quality of outcomes without requiring complex analytics.
How to set review intervals and adjust strategy
Set fixed review intervals that match your typical sample speed. Avoid reacting to very small samples. When reviews show a persistent mismatch between expected and realized outcomes, make small, documented adjustments to filters or sizing and then retest on a fresh sample.
Consistent measurement and disciplined reviews keep you honest about both win rate and expected value, and they reduce the chance of abandoning a sound strategy after short-term noise.
Both positive expected value and a high win rate have legitimate roles depending on your objective, bankroll, and the constraints of a challenge. Favor expected value when your time horizon and bankroll allow it, and favor win rate when short-term survival is critical.

Whatever you choose, document decisions, use repeatable sizing rules, and measure performance with a compact set of metrics. Responsible participation and steady iteration are the most reliable ways to improve over time.
Expected value measures average long-term edge per selection, while win rate measures how often selections win. One shows average benefit, the other shows frequency.
Not always. Higher expected value can require accepting more variance. Choose based on time horizon, bankroll, and platform evaluation rules.
Keep a short performance log with selection rationale, estimated edge, stake, result, and periodic reviews to compare realized outcomes with expectations.
References
- https://analytics.bet/articles/how-winners-win-a-framework-for-breaking-down-expected-value/
- https://www.rebelbetting.com/faq/expected-value-and-variance
- https://sportshandle.com/expected-value/
- https://www.fundedplays.com
- https://www.fundedplays.com/blogs
- https://www.fundedplays.com/blogs/how-fundedplays-evaluations-work
- https://www.fundedplays.com/challenges