

How to Track Your Progress During an Evaluation: define purpose and intended use
Start by stating the evaluation purpose and intended use clearly, because what you plan to do with results determines which measures are credible and actionable. The Centers for Disease Control and Prevention highlights that defining indicators, collection approaches, and intended use up front makes progress tracking more likely to produce usable findings CDC's Program Evaluation Framework.
Next, list the primary users of progress information and the decisions they will take when signals appear. Identifying stakeholders, owners, and the decisions they need to make prevents common measurement traps where teams collect data that nobody uses. Keep this mapping concise: user, decision trigger, and likely action.
Why defining purpose matters
Purpose narrows scope and protects against collecting unnecessary variables that add noise. A short purpose statement-two sentences-helps you reject indicators that do not link to a decision. That discipline is central to any credible evaluation and saves time when you start running routine checks.
What 'intended use' means for progress tracking
Intended use is about who will act on the information and how. For example, a weekly snapshot for operations should be different from a quarterly report used for strategic funding decisions. Make the difference explicit so you can tune granularity, latency, and the level of statistical rigor to each use case.
Quick checklist before you start
Before you collect a single datapoint, confirm: objectives, scope, timelines, resources, and responsible owners. Record this startup checklist in a single document so the team can refer back when questions about definitions arise. A brief, dated checklist protects you from definition drift later.
Get the startup checklist and explore FundedPlays Challenges
Download the one-page checklist in the Summary section to get started quickly.
Keep the initial checklist light. If you try to answer every question up front you will stall; focus on the minimum needed to begin: core questions, primary users, and the first set of indicators.
Set clear indicators and baselines
Choose indicators that are specific, measurable, and directly tied to the evaluation purpose rather than vague aspirations. The CDC guidance recommends picking indicators that can be measured credibly and that will be used to inform decisions CDC's Program Evaluation Framework.
Document a baseline for each indicator and record how and when it was measured. Baselines provide the reference needed to tell whether later changes are meaningful; without them you risk chasing normal variation instead of true shifts. Where possible, record a short note on data source, collection method, and any limitations.

Characteristics of good indicators
Good indicators are precise, with clear numerators and denominators, and they change with the outcomes you care about. Prefer rate- or ratio-based measures to raw counts when volume varies over time. Tie each indicator to a decision rule so it is clear what a signal will prompt in practice.
How to set and document baselines
For every indicator, write a one-line decision rule: what will we do if the indicator moves X in Y direction. If the action requires investigation rather than immediate change, say so. Explicit decision rules reduce hesitancy and ensure that measurements lead to consistent responses.
Choose metrics and scoring rules for predictive evaluations
When evaluating predictive performance, use scoring rules that reward accurate probability estimates and consistent calibration rather than raw wins and losses. Strictly proper scoring rules remain the recommended foundation for assessing predictive accuracy over time Statistical Science on proper scoring rules.
Pick a small set of metrics you will track consistently: a calibration measure, a Brier-like score or equivalent, and a simple hit rate. Keep the set compact so you can explain trade-offs and avoid overfitting your review process.
Structure tracking around a clear purpose, a small set of indicators with baselines, consistent logs, conservative signal rules, and a review cadence that balances fast feedback with periodic deep analysis.
Translate continuous scores into bands for routine reviews: for example, define performance bands such as 'needs attention', 'on track', and 'exceeds expectations' using percentile or historical distribution cut-points. When you convert scores into bands make sure you document the method and the date so later comparisons remain valid.
Why scoring rules matter for prediction accuracy
Proper scoring rules discourage hedging and reward well-calibrated probability estimates. By choosing a stable scoring rule you create a common language for performance discussions and reduce ambiguity during reviews.
Common proper scoring rules and when to use them
Balance sophistication and interpretability. Formal scores are useful for technical reviews; simpler metrics like hit rate help non-technical stakeholders grasp direction of change. Document which audiences get which metrics to avoid confusion.
Translating scores into performance bands
Convert numeric scores into bands only after you have a reliable baseline distribution. Use bands for routine reporting and retain raw scores in logs for deeper analysis when needed.
Build a data collection and logging plan
Specify responsibilities: name the person or role that records each entry, set frequency expectations, and define a basic quality check routine. Quality checks can be simple: completeness, plausible ranges, and cross-reference with source files.
What to log and why
Capture the minimal fields that let you reconstruct events: date/time, event or case identifier, prediction or metric value, outcome when available, and a short context note that explains atypical conditions. Those fields let you filter for subsets and investigate outliers later.
Templates for consistent daily or event-level logs
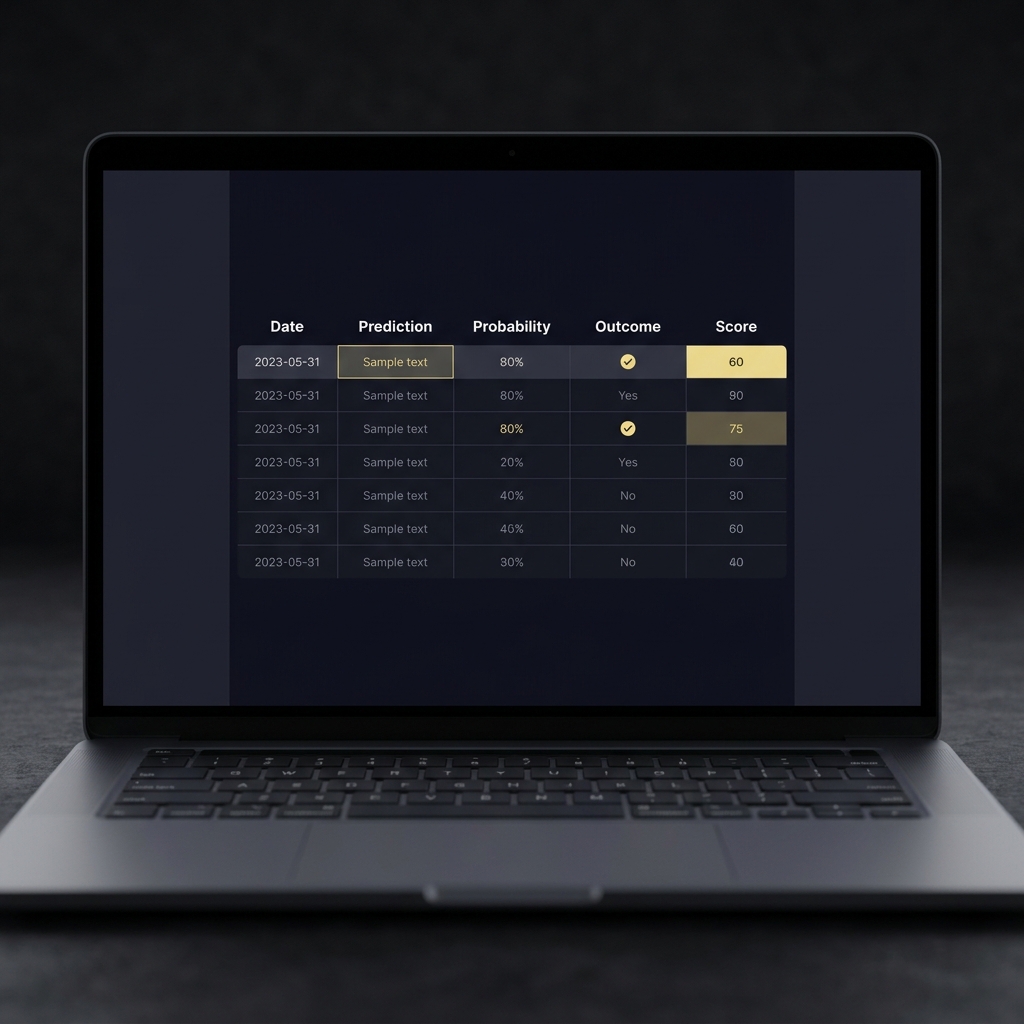
Use a simple table with column headers matching your essential fields. For prediction challenges include columns for probability, predicted outcome, actual outcome, score, and notes. Consistent templates reduce interpretation errors and make aggregation straightforward.
Responsibilities and data quality checks
Assign one data steward to review entries weekly and to file any corrections with a dated change log. Preserve original raw logs alongside any cleaned or aggregated files to maintain traceability and an audit trail.
Decide review cadence: weekly check-ins to quarterly deep-dives
Match review frequency to the tempo and risk of the evaluation. Short, recurring reviews enable quick course corrections while periodic deep analyses reveal trends and structural issues. The NHS PDSA practice shows that short cycles are effective at enabling adjustments while keeping a documented trail of what changed and why NHS England on PDSA cycles.
For programs with fast-moving data, a weekly operational check plus a monthly synthesis and a quarterly strategic review is a sensible default. Weekly checks can be lightweight; quarterly reviews should include trend analysis and any recommended redesigns. The Project Management Institute links regular performance reviews and clear success measures with better outcomes, which supports making reviews routine rather than ad hoc PMI's Pulse of the Profession 2024.

FundedPlays is an example of a skills-based challenge platform where participants track predictive performance in structured evaluations; using such simulated challenge formats can clarify what to measure and when to review, without implying guaranteed outcomes.
Matching cadence to risk and tempo
High-risk or high-variability contexts need shorter review cycles to catch problems early; low-risk, slower-moving programs can rely more on monthly or quarterly checks. Choose frequency that program staff can sustain without undue reporting burden.
What to review at each cadence
Weekly: key indicators, any signals crossing thresholds, and corrective actions. Monthly: aggregated trends, data quality issues, and candidate adjustments. Quarterly: deeper root-cause analysis, revisions to indicators, and strategic decisions.
Balancing lightweight reviews with deeper analyses
Design lightweight templates for weekly checks and reserve detailed analyses for monthly or quarterly sessions. The aim is to preserve time for action while ensuring deeper investigations happen regularly and are well documented.
Use control charts and signal rules to interpret variation
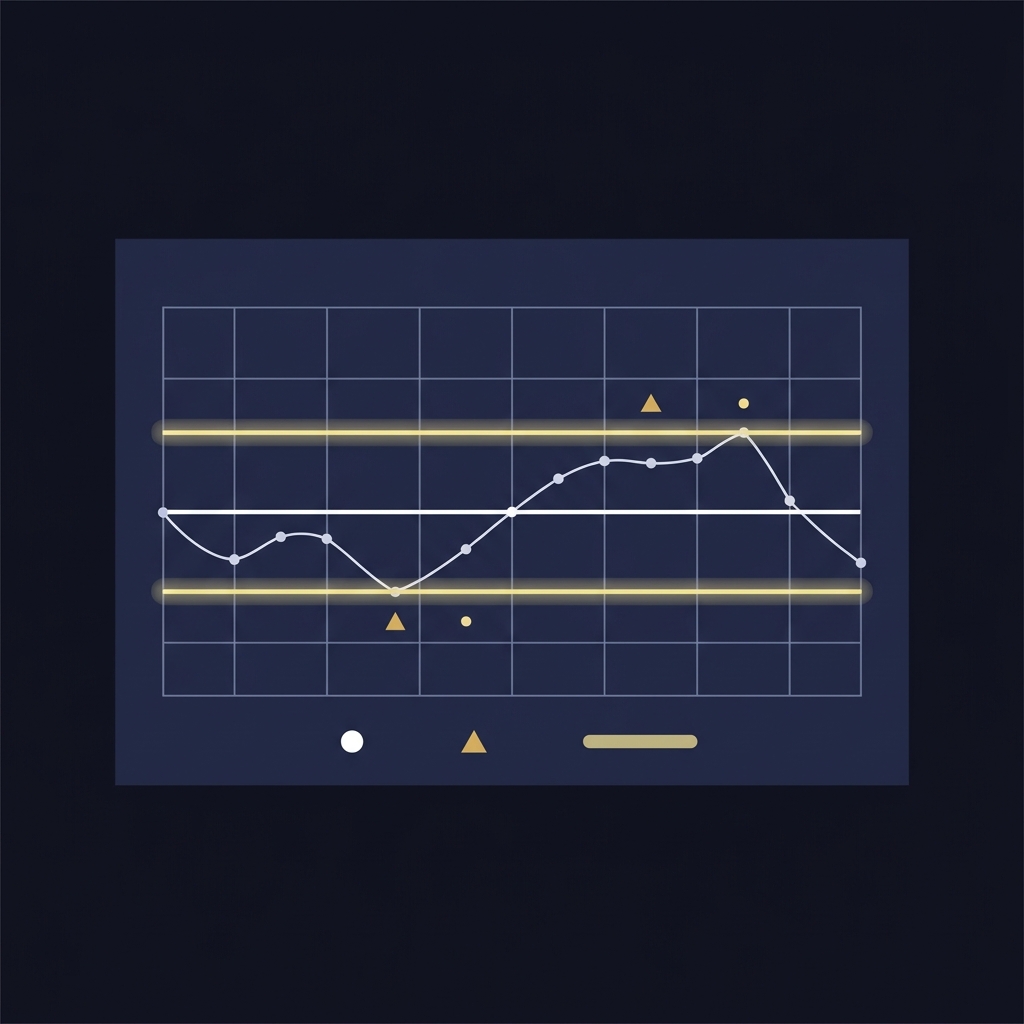
Control and run charts help distinguish common cause variation from special cause signals; using baselines and conservative signal rules reduces the chance of false alarms and unnecessary changes NHS England on statistical process control.
When you set signal rules, prefer conservative thresholds during early implementation so you avoid chasing routine noise. If sample sizes are small or data are irregular, be cautious about over-interpreting apparent signals and consider complementing charts with context notes from logs.
Basics of control/run charts for evaluation data
Plot a simple time series with a baseline and control limits to show expected variation. Annotate the chart with events or changes that could explain shifts, because charts alone do not prove causation.
Setting signal rules to avoid false alarms
Use a small set of clear rules, for example sustained runs or points outside control limits, and document why you chose them. Conservative defaults help keep your team from reacting to ordinary fluctuation.
When variation indicates real change
Look for recurring patterns or sustained movement rather than single outliers. When multiple indicators show consistent direction over a meaningful period, treat the pattern as evidence warranting investigation.
Design a simple progress tracker template
Structure the tracker with a header (purpose and baseline), a data table, simple charts, and an action log so each entry links to a decision and follow-up. A modular template is easier to adapt across different challenges and audiences CDC's Program Evaluation Framework.
For prediction challenges keep minimal fields: date, event, prediction, probability, outcome, score, and notes. That set supports both quick weekly snapshots and later aggregation for calibration analysis.
Single-sheet tracker template to capture prediction events and actions
Use this as a start and adapt fields to local definitions
Visual cues help readers spot trends. Add a small sparkline beside key indicators, trend arrows for direction, and a flag column for rows that triggered investigation. These visual cues reduce friction during short reviews.
Core sections of a tracker
Keep the header concise with purpose, baseline date, and definitions. The data table should align with essential fields and the action log should record who did what and when, including any hypothesis tested.
Minimal fields for a prediction challenge tracker
Required columns are: timestamp, event id, prediction or probability, outcome, scoring metric, and notes. Keep optional columns for context-only details that analysts can add when needed.
Examples of visual progress cues
Sparklines show short-term direction, trend arrows summarize last N points, and control limits on small charts flag potential signals. Use simple graphics that can be read at a glance in a weekly snapshot.
Run short cycles and keep an audit trail (PDSA in practice)
Adopt short Plan-Do-Study-Act cycles to test small changes and capture learning. PDSA-style rapid cycles let teams try low-cost adjustments, observe results, and decide whether to adopt or abandon changes, while keeping clear documentation NHS England on PDSA.
Record each test with a hypothesis, the change applied, the observed outcome, and the decision that followed. Over time this audit trail becomes a compact institutional memory that helps teams learn without repeating avoidable mistakes.
Running rapid test cycles
Keep tests small and time-boxed. A brief hypothesis, defined measure, and a stop rule reduce wasted effort and make it easier to compare tests across time.
Documenting tests and decisions
Log the hypothesis, dates, results, and any approved next steps. Include links to supporting charts and raw logs so reviewers can reconstruct what happened if questions arise later.
Using results to update plans
Use the documented results to update indicators, thresholds, or the tracker itself. When a change becomes standard practice, record the definition change in a versioned change log to preserve reproducibility.
Common mistakes that distort progress tracking
Reacting to single data points without considering control limits can produce false alarms. NHS guidance on SPC emphasizes baselines and conservative signal rules to avoid overreacting to routine variation NHS England on statistical process control.
Changing indicator definitions midstream without documenting the date and rationale creates definition drift and undermines credibility. Always record changes in the tracker version history and flag affected periods for reanalysis.
Reacting to routine variation
Resist the urge to change practice after a single outlier. Check logs, context notes, and control charts before initiating corrective actions.
Changing indicators midstream without documentation
If you must change an indicator, document the old definition, the new one, the date, and the reason. That documentation allows later teams to interpret historical trends correctly.
Overly complex trackers that nobody uses
Collect only fields you will use regularly. If a tracker is too heavy it will not be maintained and your progress tracking will deteriorate. Prioritize usability over completeness.
Decision criteria: when to course-correct, pause, or double down
Write decision thresholds that combine statistical signals with contextual rules so actions are both defensible and practical. For example, require both a signal on a control chart and corroborating context notes before a major course-correction; this reduces noisy reactions and preserves credibility NHS England on statistical process control.
Map an escalation path: who receives alerts, who investigates, and who approves changes. Keep escalation levels simple and document approval roles so decisions are timely and auditable.
Creating clear thresholds
Define thresholds as combined conditions whenever possible, such as score decline plus increased variance. Combined rules help separate meaningful shifts from short-term noise.
Escalation paths and approvals
Assign roles for triage, investigation, and approval. A named investigator who can pull logs and produce a short memo speeds decision-making compared with an open-ended committee process.
Weighing short-term noise against long-term trends
When in doubt, prioritize patterns over isolated points and document the rationale for any major change. That written rationale becomes part of your audit trail and supports learning.
Examples and scenarios: a prediction challenge tracker in practice
Scenario: improving calibration over a month. A team tracks calibration metrics and probability bins, logs each event, and runs weekly PDSA tests on forecast templates. The consistent logs and scoring rules make gradual improvements visible in the monthly trend, and documentation shows which changes correlated with better calibration Statistical Science on scoring rules.
Scenario: detecting a sudden drop in hit rate. A weekly snapshot flags a decline in hit rate; the investigator checks raw logs, event context, and recent definition changes before recommending a pause on a new approach. Because the team kept an audit trail, they could trace the drop to an external event rather than an internal process failure.
How the tracker guided decisions without overreacting: in both scenarios the combination of scoring rules, logs, and conservative signal rules helped the team choose proportionate responses and document learning for future reference.
Scenario 1: improving calibration over a month
Small, documented adjustments to model inputs or forecast framing, followed by weekly checks, help teams iteratively improve calibration. Keep tests small and record the effect on both calibration and broader performance bands.
Scenario 2: detecting a sudden drop in hit rate
Investigate context quickly: check for definition changes, data quality issues, or external factors. Use the audit trail to confirm whether the drop is persistent before initiating larger changes.
How the tracker guided decisions without overreacting
Well-documented scoring and consistent logging provide the evidence needed to choose measured responses rather than ad hoc fixes. That approach preserves credibility with stakeholders.
How to report progress to stakeholders
Tailor reports to audience needs. Technical teams want raw scores and logs, program managers prefer takeaways and recommended actions, and executives need one-line summaries and clear asks. Design a cover note that situates the snapshot in context and summarizes uncertainty concise and plainly CDC's Program Evaluation Framework.
A short weekly snapshot template should include the headline signal, one-line context, recent action taken, and the recommended next step. Reserve detailed tables and charts for monthly and quarterly packages where reviewers have more time.
Tailoring reports to audience needs
Use different versions of the same data: raw logs for analysts, aggregated charts for managers, and single-slide summaries for executives. Keep language consistent about what a signal means and what action you propose.
A simple weekly snapshot template
Include: top-line status, recent flags, short rationale, and required decisions. Keep it to one page so recipients can act quickly.
What to include for executive summaries
State the status, trend direction, key risk, and a concise recommendation. Avoid technical detail in the headline; add an appendix for reviewers who want to dig deeper.
Maintaining integrity: logs, reproducibility, and transparency
Use version control for tracker templates and record definition updates with dates and authors. Preserve raw logs and keep a change log to support audits; reproducibility is a function of clear versioning and accessible raw data Statistical Science on scoring methods.
Store raw logs alongside cleaned datasets and document every transformation. Transparent methods and clear notes about limitations strengthen the credibility of your progress claims and make post-hoc reviews faster and fairer.
Version control for trackers and definitions
Keep dated copies of tracker templates and record who made changes. A simple versioning scheme and a short change note are usually sufficient for most teams.
Storing raw data and change logs
Preserve original exports and append a change log with every edit. That archive is the basis for reproducible answers to later questions.
Auditability best practices
Ensure at least one person knows how to pull raw logs and link them to published snapshots. Regular spot checks of the audit trail keep practices honest.
Summary checklist and next steps
One-page startup checklist: confirm purpose and intended use, list primary users and decisions, choose 3 to 6 core indicators, record baselines, build a minimal tracker, set review cadence, and write decision thresholds. Keep this checklist on a single sheet to make it actionable.
Suggested first actions for the next 30, 60, 90 days: 30 days-define purpose, users, and pick indicators; 60 days-establish baselines, begin weekly logging, and run first PDSA cycle; 90 days-review quarterly trends, refine thresholds, and version the tracker based on lessons learned. For deeper methods consult the frameworks listed earlier for practical guidance IISD's tracking progress report and UNDP's 8 tips on MEL, and see OECD evaluation guidance.
Keep the checklist visible and review it after each major update to ensure your tracking remains fit for purpose. That small habit delivers outsized value in maintaining trust and clarity.
Match cadence to risk and tempo: weekly lightweight checks with monthly syntheses and quarterly deep reviews are a common, sustainable approach.
At minimum capture date, event, prediction, probability, outcome, score, and a short context note to support later analysis.
Control charts set baselines and signal rules so teams respond to sustained patterns rather than isolated variation, lowering the risk of overreaction.
References
- https://www.cdc.gov/evaluation/framework/index.htm
- https://projecteuclid.org/journals/statistical-science/volume-22/issue-3/Strictly-Proper-Scoring-Rules-Prediction-and-Estimation/10.1214/07-STS242.full
- https://www.england.nhs.uk/improvement-hub/publication/plan-do-study-act-pdsa/
- https://www.pmi.org/learning/thought-leadership/pulse/pulse-of-the-profession-2024
- https://www.fundedplays.com/challenges
- https://www.england.nhs.uk/ourwork/tsd/improvement-hub/resources/statistical-process-control/
- https://www.oecd.org/dac/evaluation/evaluation-systems-in-development-co-operation.htm
- https://www.iisd.org/publications/report/tracking-progress-mel-nap-processes
- https://www.adaptation-undp.org/8-tips-building-effective-monitoring-evaluation-and-learning-systems-adaptation
- https://www.mathematica.org/solutions/monitoring-evaluation-and-learning
- https://www.fundedplays.com
- https://www.fundedplays.com/blogs
- https://www.fundedplays.com/blogs/how-fundedplays-evaluations-work