
How Injuries Should Be Weighted in Forecasts: quick overview and what this guide covers
How Injuries Should Be Weighted in Forecasts should start with a clear premise: player availability matters, and forecasts improve when expected absences are treated as probabilistic, outcome-relevant inputs. The evidence linking availability and team results supports assigning nonzero weights to anticipated missed time, and standardized time-loss recording makes those weights comparable across teams and seasons IOC consensus statement
This guide summarizes practical steps modelers can implement: map public status labels to preliminary probabilities, apply diagnosis-specific time-loss priors, and translate expected missed minutes or games into team-level performance deltas using a replacement-player framework. The goal is a transparent pipeline that is easy to validate and recalibrate.
lightweight startup checklist for injury weighting
start simple and iterate
Defining terms: injury burden, time-loss, availability and how they map to forecasts
Clear definitions reduce confusion when different data sources use varied language. Injury burden here means the aggregate effect of time-loss severity and exposure-based rates on player availability; standardized recording allows comparison across teams and seasons and underpins consistent weighting decisions IOC consensus statement
Incidence and exposure-based rates describe how often injuries occur relative to playing time, while time-loss captures the number of days or matches a player is unavailable. For short-term forecasts, time-loss priors are typically more directly useful because they translate to expected missed minutes or games, which feed into match-level projections. See additional incidence estimates in recent reviews The Incidence and Burden of Time Loss Injury
Operationally, availability is a probabilistic measure: the likelihood a listed player appears in the match and the expected minutes if they do. Modeling availability as a probability distribution rather than a binary available/unavailable label gives forecasts the flexibility to reflect uncertainty and to combine signals from status reports, medical priors and context.

Official status signals and reporting cadence: mapping league reports to probabilities
Public league reports offer structured categories and a predictable cadence that forecasting systems can use as recurring signals. For example, both the NFL and the NBA publish participation or injury-report guidance that modelers can map into preliminary status labels before calibration 2023 NFL Injury Report Policy
Reporting cadence matters. A status published three days before a match has different informational value than an announcement the night before; models should weight recency accordingly and treat older reports as weaker signals when more recent updates are available.
Practical mapping starts with a conservative table that translates each public label into a preliminary probability range and a note on uncertainty. Use that table as an initial prior and annotate each mapping with its source cadence so downstream steps can adjust weights by recency and context.
See structured challenge rules and evaluation at FundedPlays
If you want a ready-to-adapt mapping table, download a template mapping table to adapt to your league and data cadence and consult the example templates later in this article.
Diagnosis-specific priors: using historical time-loss by injury type
Diagnosis matters. Recent European football reporting shows muscle injuries dominate unavailability and are therefore a practical place to start when forming time-loss priors for football-model pipelines Men's European Football Injury Index 2023/24. See time-before-return data for common injuries Time before return to play for the most common injuries
Where possible, extract diagnosis-specific time-loss distributions rather than single point estimates. A distribution can express the most likely missed time, tail risk for long layoffs, and variance that will be important for communicating uncertainty to stakeholders.
Represent priors as probabilistic distributions-for example a discrete distribution over matches missed or a continuous distribution over days out-so they can be updated with current-season data and combined with status signals in a Bayesian or empirical-Bayes workflow.
A practical modeling framework: combining status signals with priors to produce calibrated injury weights
Start with a single usable formula: a public status signal multiplied by a diagnosis-based time-loss prior, adjusted for context covariates, yields an availability probability that feeds forecasts. This core idea keeps the pipeline auditable and modular IOC consensus statement
Convert status labels into preliminary probabilities, apply diagnosis-specific time-loss priors, adjust for context covariates, and translate expected missed time into a replacement-level performance delta; then validate the whole pipeline out of sample.
Step 1, ingest the latest status labels and normalize them to your status taxonomy. Step 2, attach a diagnosis-specific time-loss prior if diagnosis is available. Step 3, adjust that combined signal for context covariates such as schedule congestion or recent minutes. Step 4, convert the resulting expected missed time into a replacement-level performance delta and inject that into your match model. For an example of an evaluation workflow, see how Funded Plays evaluates systems how Funded Plays evaluations work
When adding covariates, treat them as modifiers rather than replacements for the prior. For example, evidence suggests that schedule congestion can increase risk or extend recovery times; use a small multiplicative modifier and estimate its size from historical data rather than assuming a fixed effect FanGraphs WAR library
Maintain a simple logging system that records the raw status, the prior used, covariates applied, and the resulting availability probability. This audit trail is essential for explaining forecast changes and for debugging cases where the injury-weighted forecast moves in unexpected directions.
Translating missed time into performance impact: replacement-level approaches
Replacement-level frameworks provide a tractable route from expected missed minutes to team-level performance impact. The idea is to estimate the difference between the absent player's expected contribution and a replacement-level substitute, then express that gap in rating points or an expected score differential FanGraphs WAR library
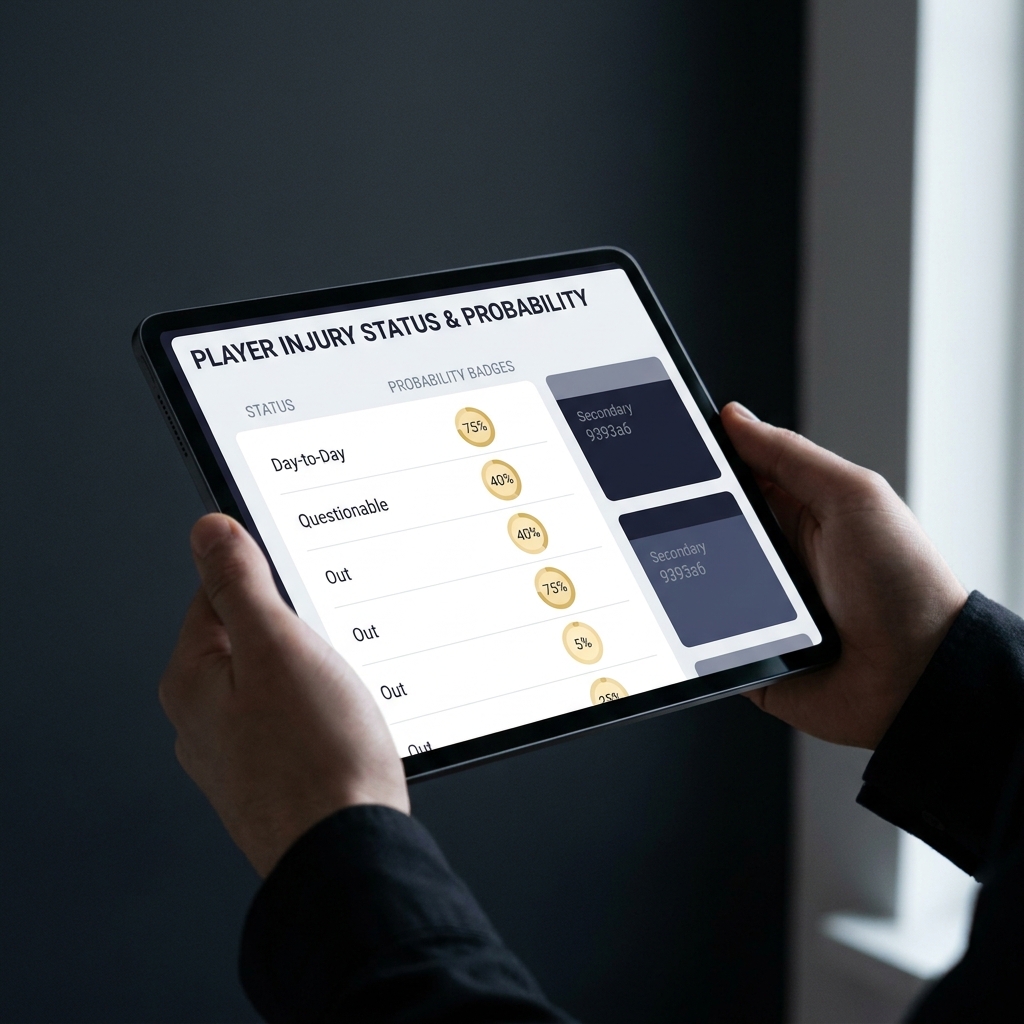
To use this approach, first estimate expected minutes or games missed from your availability probability and time-loss prior. Second, estimate the absent player's contribution per minute or per game. Third, substitute a replacement-level contribution for the missed time and compute the delta. The result is a quantifiable performance adjustment that can be added to the match model's team ratings or expected score.
Be explicit about sport-specific caveats. A single missing goalkeeper in football has different substitution dynamics than a missing rotation starter in basketball. Conversion parameters must be estimated using sport-appropriate data and validated with out-of-sample tests before being trusted in production.
Calibrating and sport-specificizing injury weights
Weights should be sport-specific. Incidence, substitution rules, and match importance vary by sport, so a one-size-fits-all scale will misstate impact across competitions. Use sport-level priors and adjust scales to reflect substitution norms and typical minutes played per role Injuries affect team performance negatively in professional football

Calibration approaches include holdout validation, time-series backtesting, and simple shrinkage toward priors when sample sizes are small. For teams or practitioners with limited event data, shrinkage toward a pooled league prior reduces overfitting while still allowing the model to learn when enough evidence accumulates. For more on evaluation practices, see the Funded Plays blog Funded Plays blog
Always validate out of sample. Calibrating on historical seasons and then testing on withheld seasons or rolling forward windows is the most defensible way to ensure injury weights add predictive value rather than merely fitting noise.
Model evaluation: metrics and out-of-sample testing for injury adjustments
Measure both the availability prediction and the downstream forecast impact. For availability, probabilistic metrics such as the Brier score or log loss quantify whether predicted participation probabilities match outcomes. For the match model, evaluate whether including injury weights improves calibration and discrimination of match outcome probabilities IOC consensus statement
Design ablation tests that remove the injury-weighting component and compare performance using consistent backtest windows. An ablation can show whether gains arise from better availability predictions or from better translation of missed time to performance deltas.
Watch for failure modes. Noisy or biased status signals can worsen match forecasts. Use monitoring alerts to detect when adding injury weights begins to degrade out-of-sample performance and then investigate whether priors, mapping tables, or covariates need recalibration. Temporal trends research documents variation in incidence across sports and contexts Temporal trends in incidence
For immediate operational use, maintain clear thresholds for triggering recalibration and automated alerts that surface unexpected signal shifts.
Common mistakes and pitfalls when weighting injuries
A frequent error is treating public status labels as certainties. Status volatility and last-minute changes mean that labels should be treated probabilistically and updated as new information arrives rather than applied as fixed outcomes IOC consensus statement
Applying one-size-fits-all time-loss values across injury types or competitions ignores clear differences in diagnosis and context. Muscle injuries often have shorter but recurring absence patterns compared with some ligament injuries, so use diagnosis-specific priors when possible and avoid hard-coded single values.
Also consider reporting biases. League policies and strategic disclosures can lead to selective visibility of injuries. Adjust priors or add uncertainty when public reporting rules or incentives create asymmetric information that could skew a naive mapping.
Practical example: applying the framework to professional football availability
Walk through a football scenario: a starter is listed with a muscle strain in a midweek report. Begin by mapping the public status to a preliminary participation probability, then apply a muscle-injury time-loss prior derived from European injury indices to estimate expected missed matches Men's European Football Injury Index 2023/24
Next, convert expected missed minutes into a team-level rating adjustment using a replacement-level framework. Estimate the absent player's per-minute contribution, subtract the replacement-level contribution, and scale the delta by expected minutes missed. This yields a performance adjustment that can be added to the pre-match rating differential.
Communicate uncertainty clearly: present a central estimate for the rating change and a plausible range based on the time-loss distribution tails. Stakeholders typically value a compact statement of directionality and confidence rather than only a point estimate.
Practical example: mapping NFL and NBA status reports to availability in model pipelines
NFL and NBA reporting rules differ in label definitions and timing, which affects how you map statuses. The NFL policy and the NBA Player Participation Policy provide the definitions and cadence that should be reflected in your mapping templates 2023 NFL Injury Report Policy
Create conservative template mappings for each league that include an uncertainty flag for labels that historically flip late. For limited-minute designations or DNP entries, convert to expected minutes ranges rather than binary outcomes so the match model can use partial-contribution logic.
For last-minute changes, treat the late update as high-information but also consider market effects when forecasts feed betting or prediction products. Where possible, automate rapid re-ingestion and re-scoring while avoiding overreacting to single-source noise.
Operationalizing: data flows, update cadence and production considerations
Balance latency and stability. Cache status signals for short windows to avoid thrashing models with minute-by-minute noise, but refresh before key scoring deadlines. Implement automated quality checks that compare new reports to expected distributions and flag anomalies for human review.
Monitor signal quality and performance drift. Track availability Brier score and the impact on match-model log loss. If signals degrade, trigger a recalibration routine that re-estimates priors and mapping coefficients on recent data.
Ethical, privacy and policy considerations when using public injury data
Respect player privacy and public data limits. Rely on publicly available reports or consented data sources and avoid attempting to infer private medical details from noisy signals. Be transparent about what data are used and what is not.
Recognize reporting biases and policy effects. When league rules shape disclosure, that can create systematic gaps that models must account for. Label forecast outputs to reflect availability uncertainty and avoid overstating confidence in player participation calls NBA Player Participation Policy
Conclusion: practical checklist to implement model-ready injury weights
Implementation checklist: define consistent injury and availability metrics, collect diagnosis-specific time-loss priors, build a status-to-probability mapping, convert expected missed time into a replacement-level performance delta, and validate the full pipeline out of sample IOC consensus statement
For immediate next steps, teams with limited data should use pooled league priors and shrinkage, while teams with rich histories can estimate sport- and role-specific conversion parameters and run holdout validations. Keep updates simple, auditable, and conservative when uncertainty is high. Visit the Funded Plays homepage Funded Plays
Map the report label to a preliminary probability using a conservative status-to-probability table, then adjust with diagnosis-specific time-loss priors and recent context such as schedule congestion.
No, use probabilistic time-loss priors by diagnosis so models capture variance and tail outcomes; shrink toward pooled priors if sample sizes are small.
Yes, if priors or status mappings are noisy or biased; use out-of-sample validation and monitoring to detect and recalibrate when performance degrades.
References
- https://bjsm.bmj.com/content/54/7/372
- https://pubmed.ncbi.nlm.nih.gov/29884595/
- https://operations.nfl.com/updates/football-ops/2023-nfl-injury-report-policy/
- https://www.howdengroup.com/uk-en/insights/mens-european-football-injury-index-2023-24
- https://bjsm.bmj.com/content/54/7/421
- https://library.fangraphs.com/war/war/
- https://bjsm.bmj.com/content/47/12/738
- https://www.fundedplays.com/challenges
- https://www.fundedplays.com/blogs/how-fundedplays-evaluations-work
- https://www.fundedplays.com/blogs
- https://www.fundedplays.com
- https://www.nature.com/articles/s41598-021-87920-6
- https://ak-static.cms.nba.com/wp-content/uploads/sites/3/2023/09/Player-Participation-Policy.pdf