
What makes cricket predictions different from other sports
Cricket predictions sit at the intersection of fixed, codified match structure and large, context-rich event streams, which makes the notion of cricket odds different from many other sports. The playing conditions set by the sport define the basic features any model will use, and those formal rules influence both pre-match and in-play probabilities, so it matters from the start how the rules are encoded.
Match length, fielding restrictions and toss procedures are not just background detail, they determine which moments in a game carry the most predictive signal and which do not. The ICC playing conditions formally codify elements such as overs per innings, powerplays, and fielding restrictions that are primary inputs when building predictive features for cricket models ICC playing conditions.
Try Funded Plays Challenges
Learn how structured, skill-based challenges let you practice forecasting discipline with virtual funded accounts without implying guaranteed returns.
Weather interruptions are a particular wrinkle in limited-overs cricket because the commonly used Duckworth-Lewis-Stern adjustments change chase targets and therefore win probability mid-game. Models that ignore DLS effects can miss abrupt shifts in state when a match is shortened or a target is revised Duckworth-Lewis-Stern method explained.
Format differences also drive predictability. Short formats like T20 compress the contest into a few overs, increasing variance and shrinking the effective sample size per match compared with ODIs or Test cricket, which generally gives a stronger statistical signal over longer samples Cricsheet.
How official rules and match format shape model features
Official playing rules translate directly into repeatable, rule-derived features you should extract before modeling. Key items to capture are innings length in overs, defined powerplay windows, fielding restriction thresholds, and toss outcomes. These items are explicitly specified in the playing conditions and form part of the model's structural assumptions ICC playing conditions.
Transform rule text into variables such as overs_remaining, powerplay_active, maximum_fielders_outside_circle, and toss_won_by. These become deterministic inputs that guide how you segment a match into phases and how you treat different overs for feature engineering.
DLS adjustments create a discontinuity in chase-state features because the target and required run rate can change instantly after an interruption. When that happens, your state representation should include both pre-interruption and post-interruption targets and an indicator for DLS_applied so that models can learn the different chase dynamics that follow a reset Duckworth-Lewis-Stern method explained.
Playing conditions are updated periodically, so a robust workflow includes a step to verify season-specific rules before assuming static values. If powerplay windows or fielding limits change between seasons, feature definitions and historical labels must be adjusted to remain valid ICC playing conditions.
Data sources and the basic workflow for building cricket prediction models
Open ball-by-ball datasets and curated statistic services are the standard foundation for cricket modeling. Public ball-by-ball repositories provide event-level detail, while curated statistic sites give convenient summaries for player and team career statistics. Together they let you construct both micro and macro features for cricket odds models
Cricket predictability depends on format, rules, and data: longer formats tend to be easier to model while short formats like T20 require wider uncertainty and careful feature engineering.
Start the pipeline with raw ball-by-ball ingestion, then canonicalize event fields such as over, ball, batsman, bowler, runs, and dismissal type. Cricsheet-style datasets are commonly used for raw events because of their structured, line-by-line format and broad coverage of matches Cricsheet.
Next, derive phase features: over_number, runs_in_over, wickets_in_over, cumulative_run_rate, and recent_batsman_form. Combine these with season-level metadata like venue records and head-to-head statistics from curated sources such as Statsguru to add context that raw ball events do not carry by themselves Statsguru.
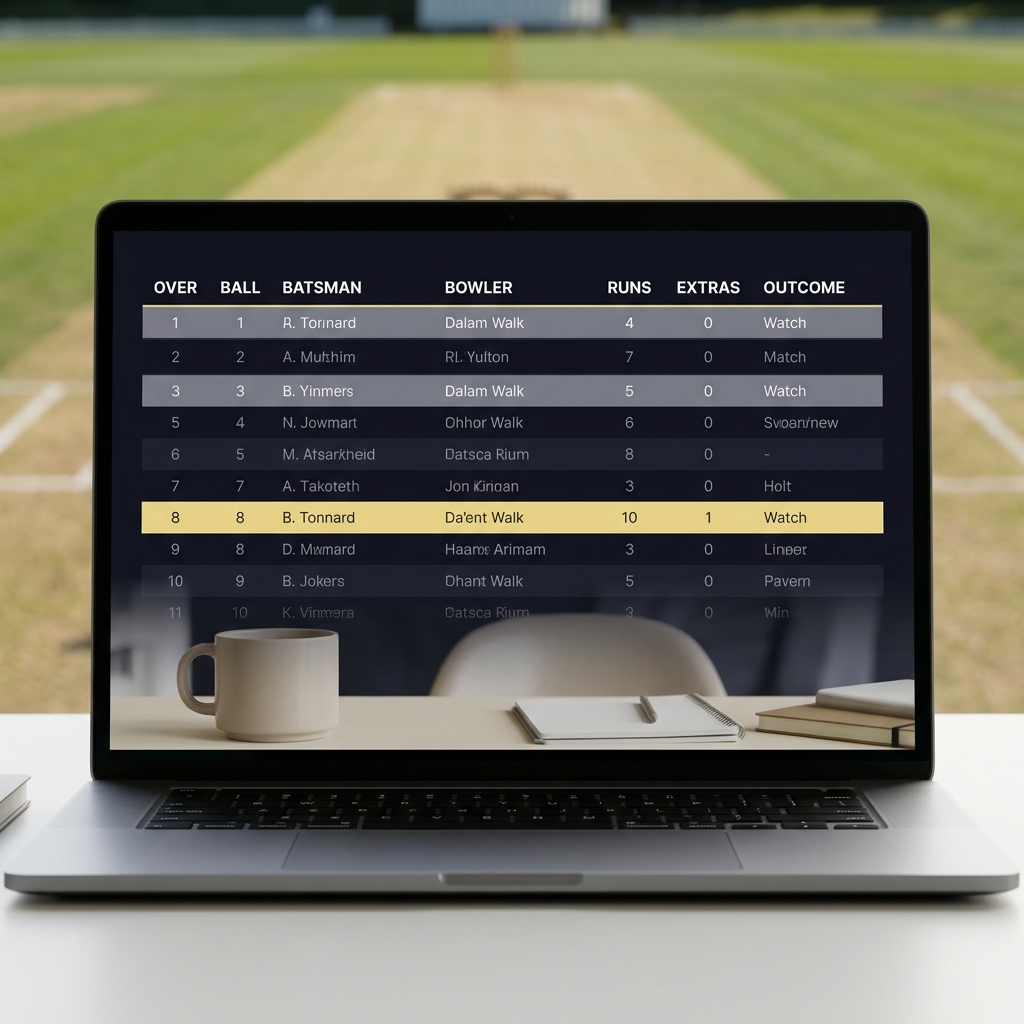
Common data quality issues include inconsistent player naming across sources, missing dismissal types, and sparse ball-level metadata for older matches. Typical cleaning steps are name resolution using mapping tables, filling missing categorical fields with an explicit unknown state, and excluding or flagging matches that lack essential metadata before training.
From baselines to machine learning: model approaches that work in practice
Begin with simple baselines. Logistic regression models and rating systems such as Elo-style approaches are helpful as sanity checks and often provide competitive performance with minimal data. These methods are interpretable and quick to iterate, making them a useful first benchmark for any cricket odds workflow.
Baseline features typically include pre-match ratings for teams, toss outcome, venue advantage, and simple recent form metrics. These baselines give a transparent reference point and make it easier to evaluate whether more complex methods actually add value.
Machine learning methods can improve on simple baselines, especially when you have richly engineered features from ball-by-ball context and player-level signals. Peer-reviewed work has shown that machine learning models can outperform simple heuristics for ODI outcome prediction on historical data, though those gains are sensitive to feature design and can degrade over time without maintenance PLOS ONE study on ODI prediction. Additional peer-reviewed analyses are available here, and specific CNN-based investigations of ball-level outcomes are discussed in academic reports here.
Practical trade-offs matter. Machine learning needs more data and careful validation to avoid overfitting to season-specific patterns. If interpretability is important, prefer simpler models or use explainability tools to surface which features drive predictions. In many applied settings a layered approach works: start with a transparent baseline, then add tree-based or regularized models and compare using proper probabilistic metrics.
How to evaluate probabilistic cricket predictions correctly
Accuracy alone is misleading for probabilistic outputs because it treats forecasts as binary calls rather than calibrated probabilities. Proper scoring rules such as Brier score and log loss measure both calibration and sharpness, which are central to judging the quality of cricket odds.
Report Brier score and log loss for held-out data and augment numeric summaries with calibration plots or reliability diagrams that show how predicted probabilities map to observed frequencies. These visual checks help detect systematic overconfidence or underconfidence in model outputs scikit-learn documentation.

When evaluating across formats, track scores separately for Tests, ODIs, and T20s, and use out-of-time validation to detect concept drift. A model that performs well on historical seasons may lose calibration if playing conditions, squad composition, or strategic trends shift.
Why shorter formats like T20 are harder to predict
In T20 cricket, the small number of overs amplifies randomness: a single over or a single wicket can flip match outcomes, which reduces the effective sample of repeatable patterns that models can learn. That higher variance lowers the ceiling for predictable structure in cricket odds compared with longer formats.
Variance, sample size, and phase effects for cricket odds
Smaller sample sizes per match mean that individual events carry more weight, so models must rely on more aggressive pooling across matches or stronger priors to make useful predictions. Phase-specific features are especially important because late overs and end-of-innings bursts disproportionately affect results in short formats Cricsheet.
For practical modeling, reflect higher uncertainty in your probabilistic outputs for T20s by reporting wider predictive intervals or softer probability estimates. Communicate that higher model uncertainty is expected in short formats and avoid over-interpreting single-match probabilities.
Common mistakes and pitfalls when building cricket odds systems
A recurring error is assuming that historical playing conditions remain constant. If a new season tweaks powerplay windows or fielding limits and you do not update your feature extraction, model inputs will mismatch reality and create biased predictions. Always verify the season's playing conditions before training ICC playing conditions.
Quick checks to avoid common modeling mistakes
Run these before training a model
Another common pitfall is data leakage, for example using post-match aggregated summaries or future information when constructing training labels. To avoid inflated performance, ensure that every feature is available at the prediction time you are modeling and use out-of-time splits to validate.
Poor calibration is also widespread. A model with high classification accuracy can still assign probabilities that are systematically off, which is why proper scoring rules and calibration checks are essential parts of any evaluation pipeline scikit-learn documentation.
Practical scenarios and next steps for readers
Simple experiments you can run: build a logistic regression that predicts match winner using recent team form, toss outcome, and venue advantage as features, train on the last two seasons, and evaluate with Brier score on the next season. That baseline gives you a clear, repeatable starting point for judging predictability and model calibration Cricsheet.
Next, compare the baseline to a more feature-rich model that adds phase-aware ball-by-ball derived features such as runs in the last two overs, wickets in the previous over, and current required run rate. Use the same out-of-time test fold and compare Brier scores and calibration plots to see whether the richer features provide practical gains scikit-learn documentation.
When you interpret results, look for consistent improvement across seasons and formats rather than a single-season bump. If performance drops or calibration worsens over time, you may be seeing concept drift and should consider retraining frequency, feature decay, or incorporating more recent data into rolling windows Cricsheet.

In summary, models can add value, but predictability depends on format, data quality, and rule stability. Short formats require more conservative probability estimates because variance is higher, while longer formats provide stronger signals but demand careful handling of season-to-season changes.
DLS can change the chase target mid-match, which shifts state variables and requires models to include the adjusted target and an indicator that DLS was applied to remain accurate.
Begin with structured ball-by-ball repositories and complement them with curated statistics; Cricsheet and summary databases are common starting points.
Machine learning can outperform simple baselines in some formats and with strong feature engineering, but gains depend on data quality and ongoing validation to manage concept drift.
References
- https://www.icc-cricket.com/about/cricket/rules-and-regulations/playing-conditions
- https://www.ecb.co.uk/news/1221052/duckworth-lewis-stern-method-explained
- https://cricsheet.org/
- https://stats.espncricinfo.com/ci/engine/stats/index.html
- https://journals.plos.org/plosone/article?id=10.1371/journal.pone.0235448
- https://scikit-learn.org/stable/modules/model_evaluation.html
- https://www.fundedplays.com/challenges
- https://pmc.ncbi.nlm.nih.gov/articles/PMC12909956/
- https://cs231n.stanford.edu/reports/2016/pdfs/273_Report.pdf
- https://www.kaggle.com/datasets/ariadaikalam/the-ultimate-ball-by-ball-cricket-dataset
- https://www.fundedplays.com
- https://www.fundedplays.com/blogs
- https://www.fundedplays.com/blogs/how-fundedplays-evaluations-work