
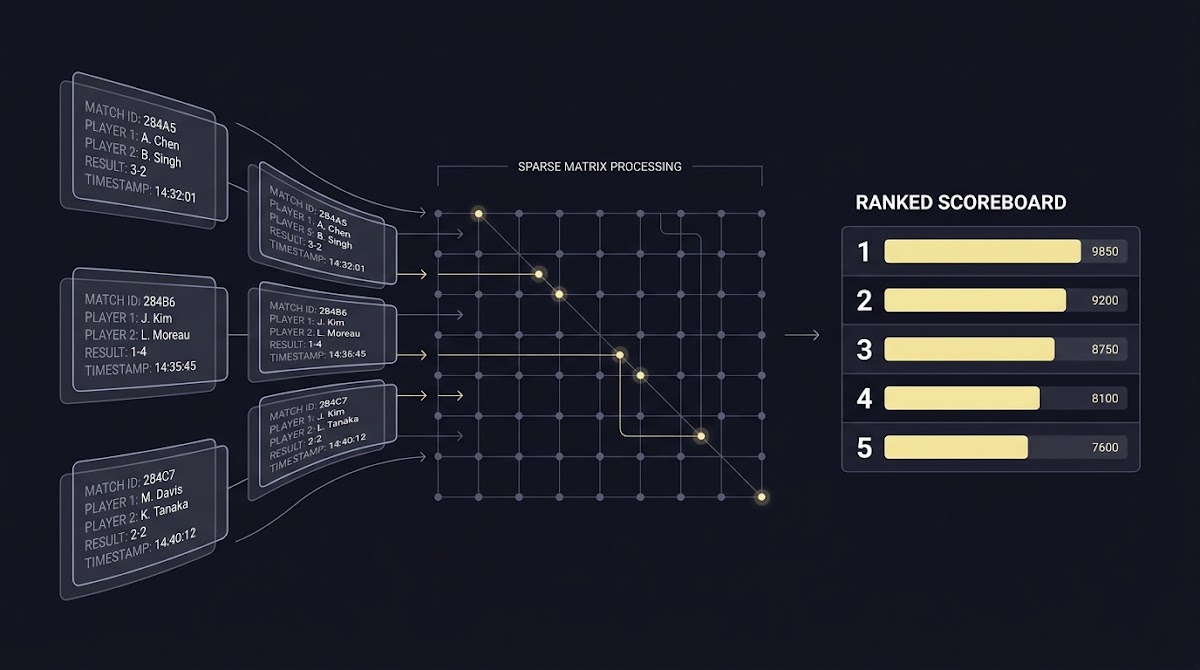
Building Power Ratings from Basic Data: overview and why they matter
A power rating is a single numeric estimate of a team or player strength that lets you compare opponents on a common scale. Building Power Ratings from Basic Data means using only routine match information such as scores, opponents, dates and venue to produce a reproducible number you can use for forecasting, ranking, or comparing performance over time.
There are two broad families of approaches. Margin-informed methods translate score differences into continuous strength estimates, while win loss approaches compress each game to a binary result and trade some information for robustness. Choosing between these depends on data quality, how much you trust reported margins, and whether you need probability outputs or just ordinal rankings.
Transparency and reproducibility matter for practical use. Methods that reduce the problem to explicit linear systems or to standard sequential update rules are easy to audit, debug, and version. When you can document the exact equations or update steps you used, other analysts can replicate the ratings and verify results without opaque model internals.
This guide focuses on practical recipes that analysts and developers can implement with minimal dependencies, explaining the assumptions behind each choice and the validation steps to check whether a chosen approach is working for your league or competition.
Building Power Ratings from Basic Data: required inputs and data checklist
Minimal data fields you need are: a stable team identifier for each side, the opponent identifier, the match date, the score for each side, and a venue or home indicator. With these fields you can derive margins, assign home or away labels, and order matches for time-aware validation.
Optional but useful covariates include competition or league identifier, game stage (regular season, playoff), rest days, and travel distance. These improve the model when available, but the core rating can be built from the minimal fields above. Keep a separate field that marks the source and any preprocessing applied so the pipeline remains auditable.
Quality checks to run before modelling include removing or flagging duplicate entries, validating that scores are numeric and within plausible ranges, checking for impossible dates, and splitting seasons consistently so inter-season comparisons are deliberate. Also confirm that each match appears once with consistent home and away roles.
Because home advantage is commonly estimated rather than assumed, preserve a recent window of matches to allow estimation. If your dataset mixes competitions with different rules or scoring conventions, keep them separate or add a competition covariate to avoid contaminating strength estimates across incompatible formats. Such care prevents biased estimates of strength and schedule effects.

Follow a ready sample CSV to reproduce the walkthrough
Download or prepare a small sample CSV that lists team, opponent, date, home flag, and scores to follow the worked example that comes later in this article.
Least-squares ratings: converting score margins and schedules into a linear system
Least-squares ratings use the idea that each observed score margin is approximately the difference between the two teams' underlying strengths plus random noise. In simplest form the model is margin = strength_home - strength_away + error. With many matches this produces a system of linear equations that can be solved for the team strengths in a reproducible way.
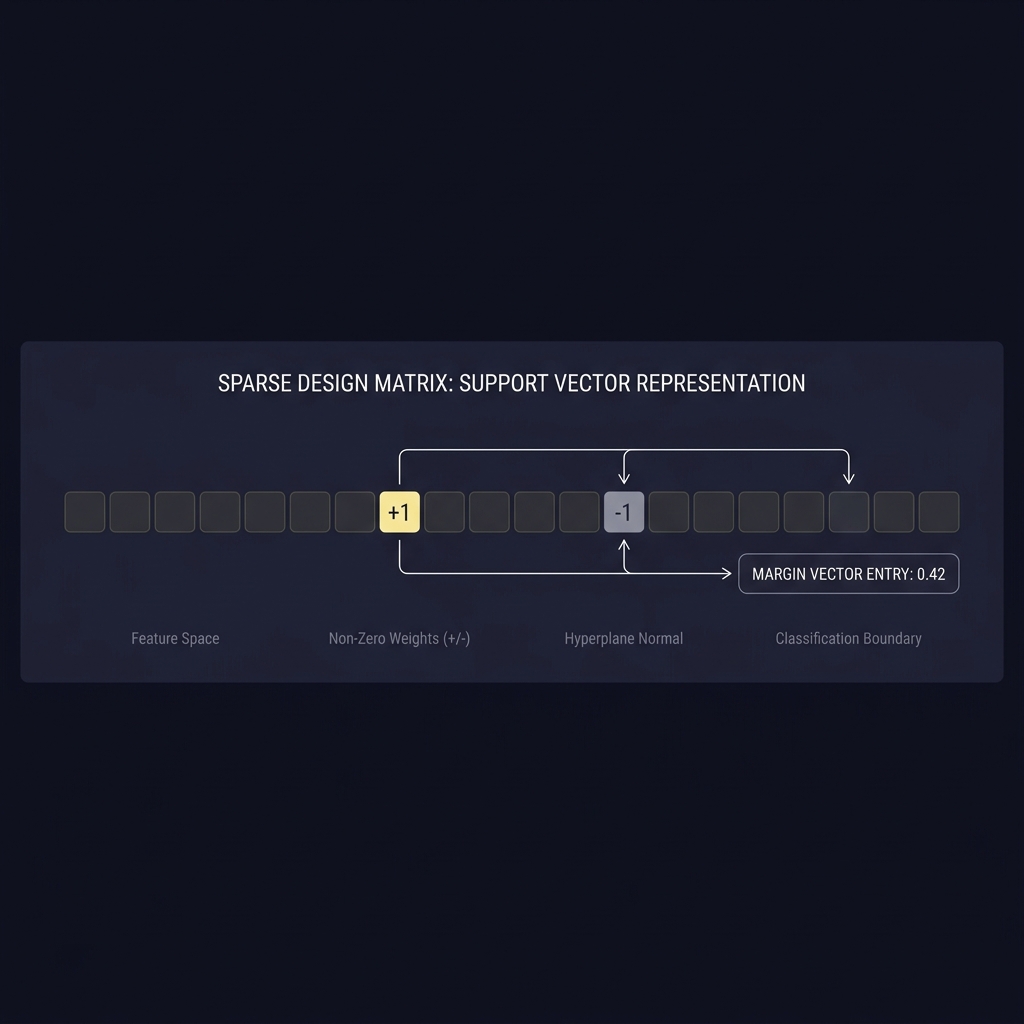
Because each match gives one linear constraint linking two unknown team strengths, stacking many matches yields a sparse design matrix and a right-hand side vector of observed margins. Solving the normal equations recovers the strengths that best fit margins in a least-squares sense. This approach is straightforward to audit because the equations are explicit and the algebraic steps are standard. For an early, widely cited exposition of margin-based ranking methods see a classic procedures paper that demonstrates this type of linear setup and its interpretability Statistical Models for College Football Rankings (see an implementation overview at Massey Rating Method Calculator).
quick solver workflow for least-squares rating assembly
start with SciPy sparse routines
Identifiability must be handled explicitly because adding a constant to every team strength leaves margins unchanged. Common constraints are to fix one team to zero or to enforce a sum-to-zero condition. Either choice pins the scale so strengths are comparable across runs and dates. Document which constraint you used so others can reproduce your numbers.
Least-squares ratings respond to actual score differences, so they reflect magnitude as well as ordering. That makes them valuable when margins are reliable and when you want ratings that map to expected margin predictions. They also provide a clear path to estimating additive effects such as home advantage within the same linear system.
Implementing the linear solver: practical steps and numerical considerations
Start by mapping each match to one row in a design matrix with columns corresponding to the teams. Represent the home team with +1 and the away team with -1 in that row. The target vector for that row is the observed margin, typically home score minus away score. If you include an intercept for home advantage, add a column with 1 for home rows and 0 for neutral or away rows.
When assembling matrices keep the representation sparse: most rows have only two nonzero entries, so use compressed sparse row formats and libraries that accept sparse inputs. For moderate sized leagues a direct sparse solver is fine; for large datasets iterative solvers with preconditioning scale better. Adding a small ridge penalty can stabilize solutions when schedules are unbalanced or when teams have few matches.
Collect a clean match log with team ids, scores, dates and venue, choose a method that fits data quality, implement explicit linear or update rules, and validate with time-aware holdouts and proper scoring rules.
Enforce identifiability by either removing one column and solving for the remaining teams relative to that baseline or by adding a sum-to-zero constraint implemented with a Lagrange multiplier or a small-ridge trick. If you add a ridge term, choose its magnitude by cross-validation or by checking sensitivity of rank order to the penalty. Keep numerical warnings visible and log condition numbers if your solver reports them.
For reproducible pipelines, separate the matrix assembly step from the solver step so unit tests can validate that rows map correctly to match records. Save both the sparse matrix and the target vector in a binary interchange format to avoid subtle preprocessing differences across environments.
Win-loss only ratings: the Colley method and when to prefer it
The Colley method builds a win-loss only linear system that yields stable ratings without using score margins. It forms a diagonally dominant matrix from win and loss counts combined with pairwise matchup counts so the resulting linear system has a unique and stable solution. When margins are unreliable or artificially inflated, this approach preserves ordinal information while reducing sensitivity to outlier scores Colley’s Bias Free College Football Ranking Method.
Construction is straightforward. Each team contributes a row where the diagonal entry is two plus the number of games played and off-diagonals are negative counts of head-to-head meetings. The right-hand side mixes wins and losses into a simple target value. Because the matrix is strictly diagonally dominant, standard linear solvers will produce a unique solution without special constraints.
Practical tradeoffs are clear: Colley discards margin information so it may miss signal present in score differences, but it can be more robust in noisy settings or when reporting conventions vary across competitions. Use Colley when match scores are inconsistent, when teams have wildly different scoring environments, or when you want a conservative baseline ranking.
When comparing Colley ranks to margin-based least-squares output on the same data you will often see similar orderings for closely matched teams, while large blowouts will influence only the margin-based ratings. That difference is the key decision point when choosing which method to deploy.
Elo and Bradley-Terry frameworks: sequential updates and expected-score models
Elo-style updates compute an expected outcome for a match using a logistic function of rating difference and then adjust both sides by a K-factor times the result error. The expected-score formulation and the role of the K-factor are standardized in modern rating rules, providing a well-understood template for implementing sequential team ratings; see the current formal specification for these expected-score updates in international rating regulations FIDE Rating Regulations (2024).

The Bradley-Terry model frames paired comparisons probabilistically. It defines the probability that team A beats team B as a function of their strength parameters, usually via a logistic link. Maximum likelihood estimation produces batch ratings that align closely with the probabilities implied by sequential Elo updates, tying the two approaches conceptually and practically Bradley-Terry Models in R: The BradleyTerry2 Package.
For systems that need probability forecasts rather than point strengths, Bradley-Terry-type models or an Elo implementation that outputs win probabilities are preferable. They support direct scoring with log loss or Brier score during validation and can incorporate covariates such as home advantage or match importance within the same likelihood framework.
Modeling home-field advantage and covariates in simple ratings
Home-field advantage can be added as an additive parameter in linear least-squares systems or as a covariate in paired-comparison likelihoods. In the linear framework add one column that is 1 for home teams and 0 otherwise; the estimated coefficient captures the average home shift on the margin scale. In Bradley-Terry or Elo frameworks include a home offset in the expected-score calculation so probabilities reflect location effects. For background on home effects see the discussion in the literature Home Field Advantage: The Facts and the Fiction.
Estimating the home advantage from recent data is better than assuming a fixed value. Home effects change over time and differ across competitions, so adopt a recent-window estimate or allow the effect to vary by season or competition. When sample sizes are small, pool across similar leagues or add a hierarchical prior to stabilize estimates.
Other covariates that matter include rest days, travel distance, and competition stage. Add them conservatively and check whether they improve out-of-sample scoring rather than only improving in-sample fit. If a covariate helps predictive metrics and calibration, retain it; otherwise prefer a simpler model.
Validation: out-of-sample testing and proper scoring rules
Validation should prioritize out-of-sample testing with time-aware splits. For seasonal sports use a training window that contains only matches that occur before your test period, and consider rolling windows to check stability over time. Avoid random shuffles that mix future data into training when the goal is forward-looking prediction.
Proper scoring rules reward both accuracy and calibration. For probabilistic forecasts use log loss or Brier score to compare models; these rules encourage honest probability estimates and make it straightforward to detect hedging or overconfident predictions. A foundational treatment of proper scoring rules and their role in estimation and evaluation is available in the statistics literature Strictly Proper Scoring Rules, Prediction, and Estimation.
Calibration checks complement scoring rules. For example, group predictions into probability bins and compare observed frequencies to predicted probabilities to see whether the model is systematically over- or under-confident. Residual analysis on predicted margins can reveal time trends or systematic misestimation that simple aggregate scores mask.
Avoiding overfitting and common model selection checks
Overfitting is a real risk in small or noisy datasets. Use regularization such as a ridge penalty in least-squares or shrinkage priors in a probabilistic model when parameter counts approach the effective sample size. Limit the number of covariates and prefer parsimonious models when validation gains are marginal.
Model selection should be driven by proper scoring rules on held-out data rather than by in-sample fit. When comparing more complex models to simpler baselines, require a meaningful and stable improvement in out-of-sample log loss or Brier score before adopting additional complexity. Keep a simple model in production if it performs comparably and is easier to explain and reproduce.
Typical mistakes and pitfalls when building power ratings
A frequent mistake is using raw blowout margins without moderation. Extreme margins can dominate least-squares estimates and distort rankings. Consider capping margins, using a robust loss function, or downweighting older blowouts when they do not reflect current team strength.
Another pitfall is mixing competitions with different scoring environments without adjustment. When leagues use different duration rules or scoring conventions, combine them only with proper covariates or separate rating pools. Failing to adjust for strength of schedule or ignoring home advantage and time decay also produces biased ratings.
Finally, neglecting validation or only judging models by in-sample fit leads to overconfidence. Always check improvements on time-aware holdouts and use calibration diagnostics to detect systematic bias before trusting deployed ratings.
Practical example: small reproducible walkthrough with toy dataset
Define a tiny match table with six matches among four teams, for example: matches where A beats B by 3 at home, B beats C by 1 away, C beats D by 2 at home, D beats A by 1 away, A beats C by 4 at home, and B draws D by 0 at neutral site. Record columns: date, team_home, team_away, score_home, score_away, home_flag. This layout is the minimal CSV you need to reproduce the examples below.
For least-squares map each row to a sparse matrix row with +1 for home team and -1 for away team and a target equal to score_home minus score_away. Solve the system with a sum-to-zero constraint to get a vector of strength values. Check that team ordering matches intuition and that magnitudes map to expected margins between teams.
For Colley transform the same six matches into win and loss counts. Build the Colley matrix and solve its linear system. You will often find that Colley ranks the teams in a similar order while compressing the magnitude differences because margins are not used. This comparison illustrates when margin information adds useful discrimination and when a win-loss only method suffices.
Sanity checks include verifying that stronger teams have higher predicted margins against weaker teams, that home advantage shifts expected margins in the correct direction, and that removing one match changes ratings proportionally rather than wildly. Save intermediate matrices so you can replay the solver and verify every step.
Implementation tips, engineering and reproducibility practices
Version data and code from the start. Store raw match logs, preprocessing scripts, and the exact matrix assembly code in a version control system. Tag releases that correspond to published rating snapshots so you can trace how a published ranking was produced.

Automate validation with rolling evaluation and unit tests for matrix assembly. Unit tests should confirm that a known small dataset produces the expected design matrix and target vector. Schedule periodic re-estimation windows and build monitoring that tracks changes in validation metrics to detect model drift.
For scaling, separate offline batch recomputation from any online update paths. Precompute matrices and cache solver outputs to speed repeated queries. Keep computationally heavy re-estimation jobs in reproducible containers and log seeds or randomness settings so results are deterministic across environments.
Conclusion and quick checklist for building power ratings from basic data
Summary: least-squares is a reproducible choice when margins are reliable, Colley is a robust win loss alternative, and Elo or Bradley-Terry frameworks are appropriate for sequential updates and probability forecasts. Always estimate home advantage from recent, relevant matches and validate using proper scoring rules.
Quick checklist: clean and version your match data, choose a method that matches data quality, implement matrix assembly or update rules clearly, validate with time-aware holdouts and proper scoring rules, and monitor production ratings for drift and calibration issues. Following these steps produces transparent, auditable team power ratings that you can trust for analysis and decision support.
At minimum you need team identifiers, opponent, match date, scores for each side, and a home indicator. Optional covariates like competition and rest days help but are not required.
Choose a win-loss method like Colley when score margins are unreliable, inconsistent across competitions, or prone to artificial inflation; it produces stable ordinal rankings without margin sensitivity.
Use time-aware holdouts, compute proper scoring rules such as log loss or Brier score for probabilistic forecasts, and inspect calibration plots comparing predicted probabilities to observed frequencies.
References
- https://masseyratings.com/papers/massey97.pdf
- https://metricgate.com/docs/massey-rating-method/
- http://www.colleyrankings.com/method.html
- https://handbook.fide.com/chapter/B022024
- https://www.jstatsoft.org/article/view/v048i09
- https://www.fundedplays.com/challenges
- https://www.chicagobooth.edu/review/home-field-advantage-facts-and-fiction
- https://doi.org/10.1198/016214506000001437
- https://www.psych.rochester.edu/research/jamiesonlab/wp-content/uploads/2014/07/JJ_JASP.pdf
- https://www.fundedplays.com
- https://www.fundedplays.com/blogs
- https://www.fundedplays.com/blogs/how-fundedplays-evaluations-work